Human-validated training data | Pilot-to-scale delivery | Multimodal coverage

Josisoft Technologies

HomeData Collection IndustriesHow We WorkAboutCareers / Join as an AnnotatorContactGet in Touch
AUDIO TRANSCRIPTION & TIMESTAMPING

Human-Reviewed Transcription Aligned Precisely to Every Spoken Segment.

Accurate speech data requires more than converting audio into text. Utterance boundaries, timing, pauses, interruptions, incomplete speech, accents, background noise, and normalization rules all affect how a dataset should be structured. Josisoft builds transcription and timestamping workflows around your language guidelines, segmentation rules, timestamp format, and QA criteria so every recording is converted into consistent, review-ready ground truth.

Talk to a Data Specialist
SPEECH DATA OPERATIONS

Core Transcription & Timestamping Capabilities

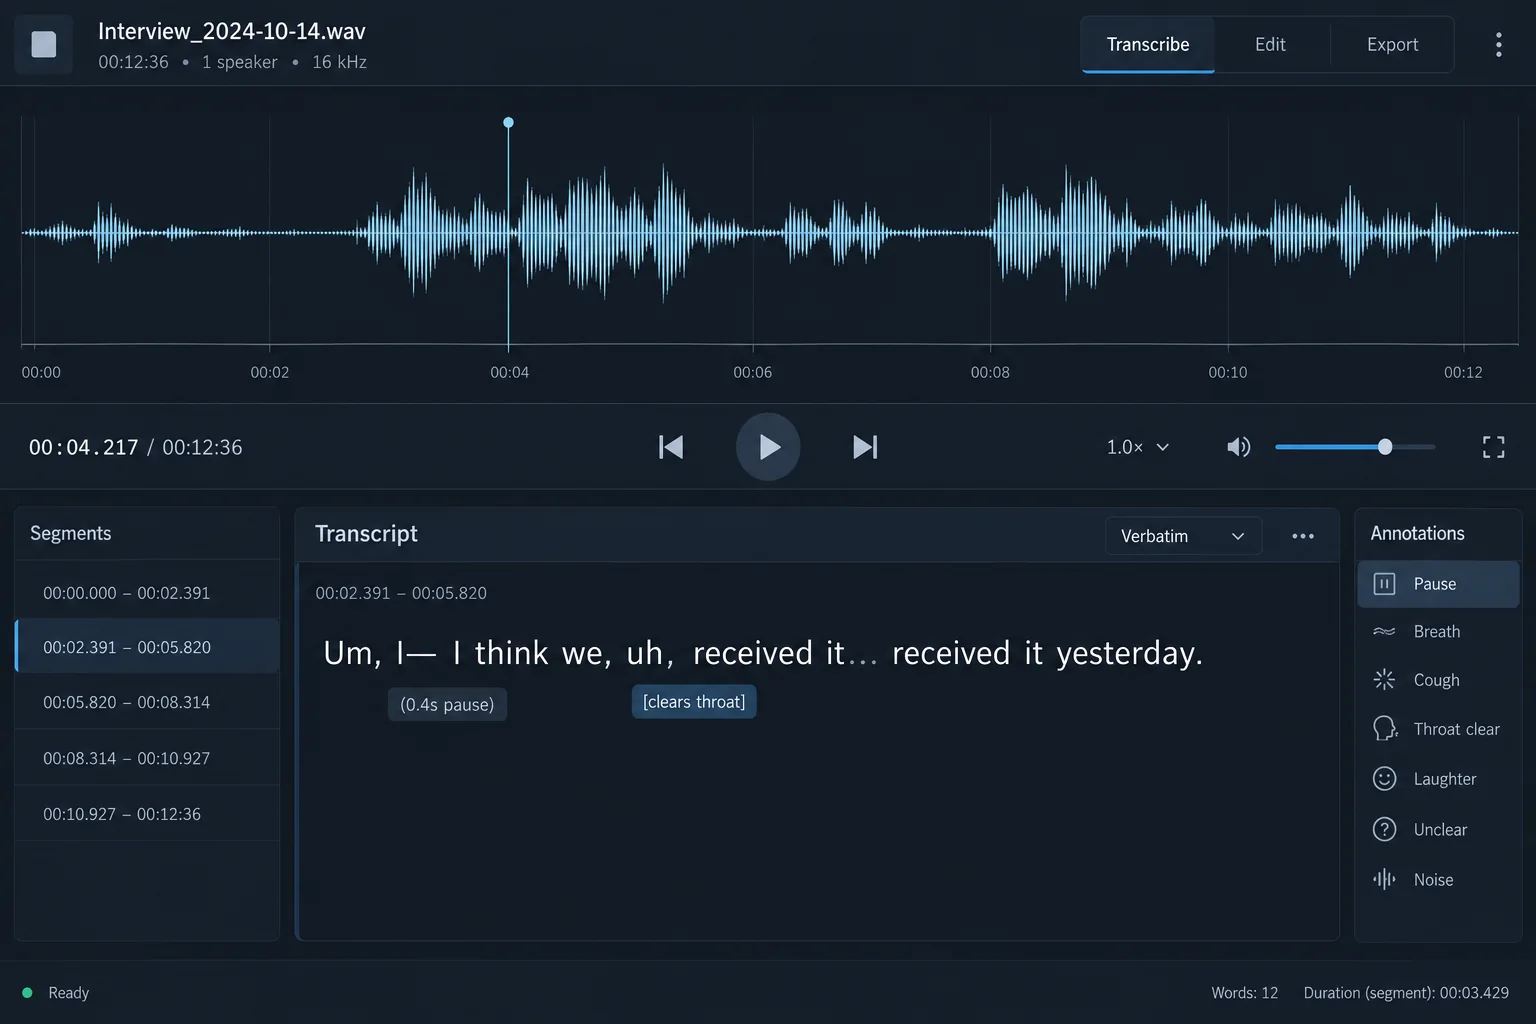
Strict Verbatim Transcription

Comprehensive acoustic-to-text transcription capturing all spoken phenomena—including stutters, false starts, fillers ("um", "uh"), repetitions, throat clearings, and conversational disfluencies for acoustic model training.

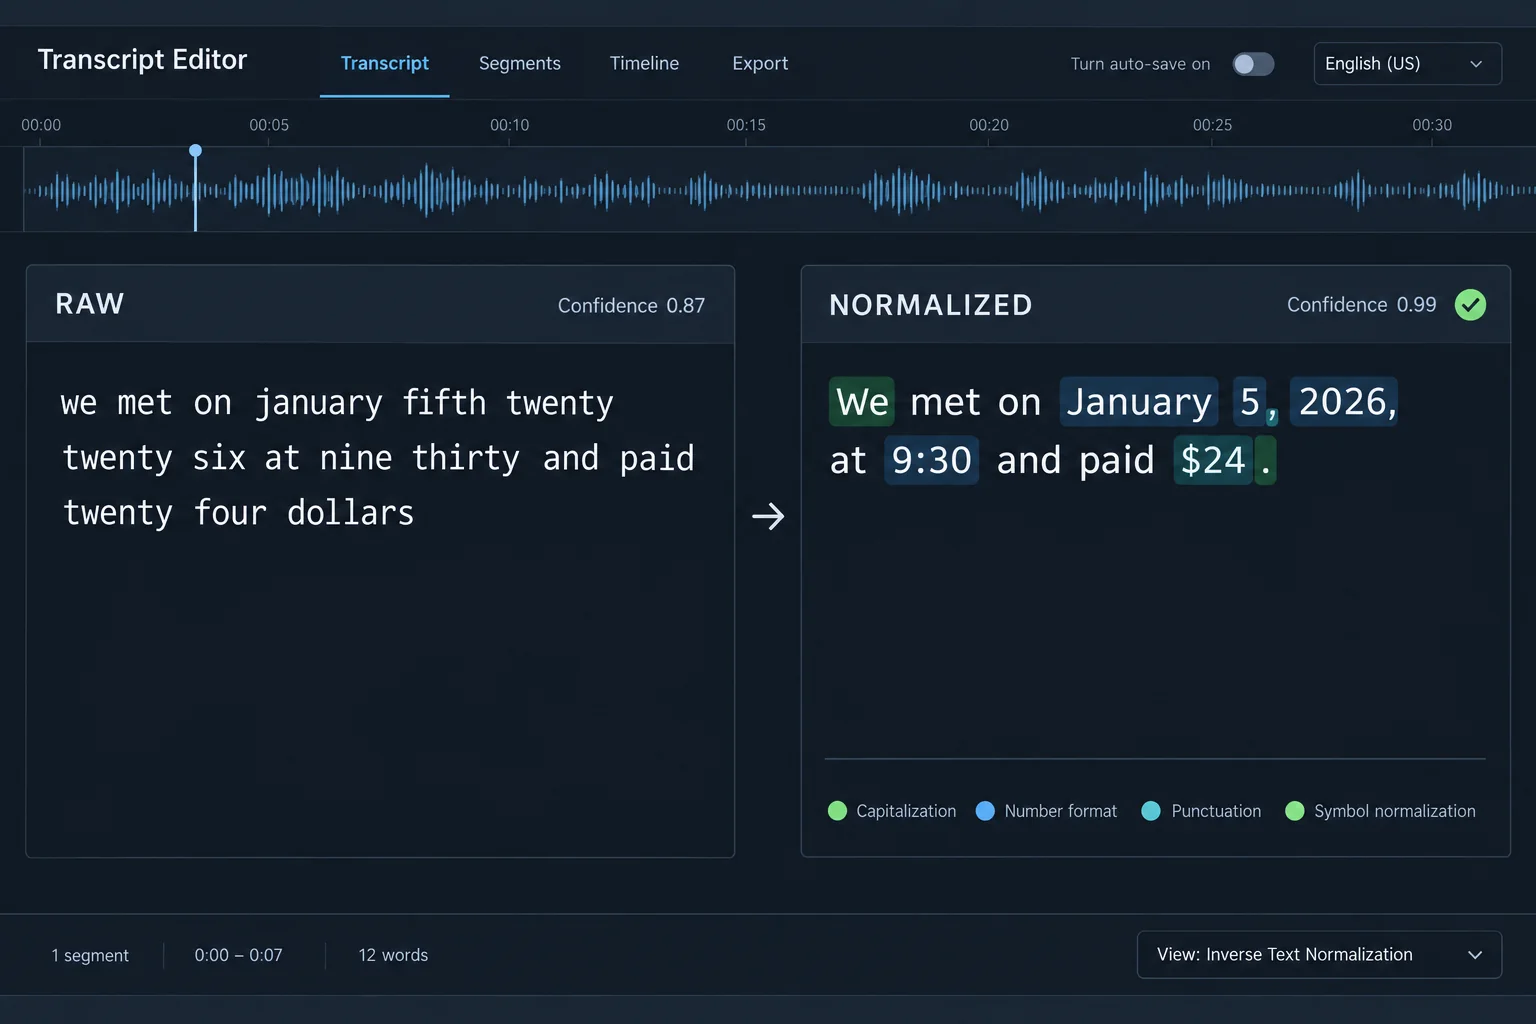
Clean & Normalized Transcription (ITN)

Standardized text transcription applying punctuation restoration, capitalization rules, disfluency removal, and Inverse Text Normalization (ITN: converting spoken numbers, dates, currencies, and acronyms into written form).

Utterance & Turn-Level Timestamping

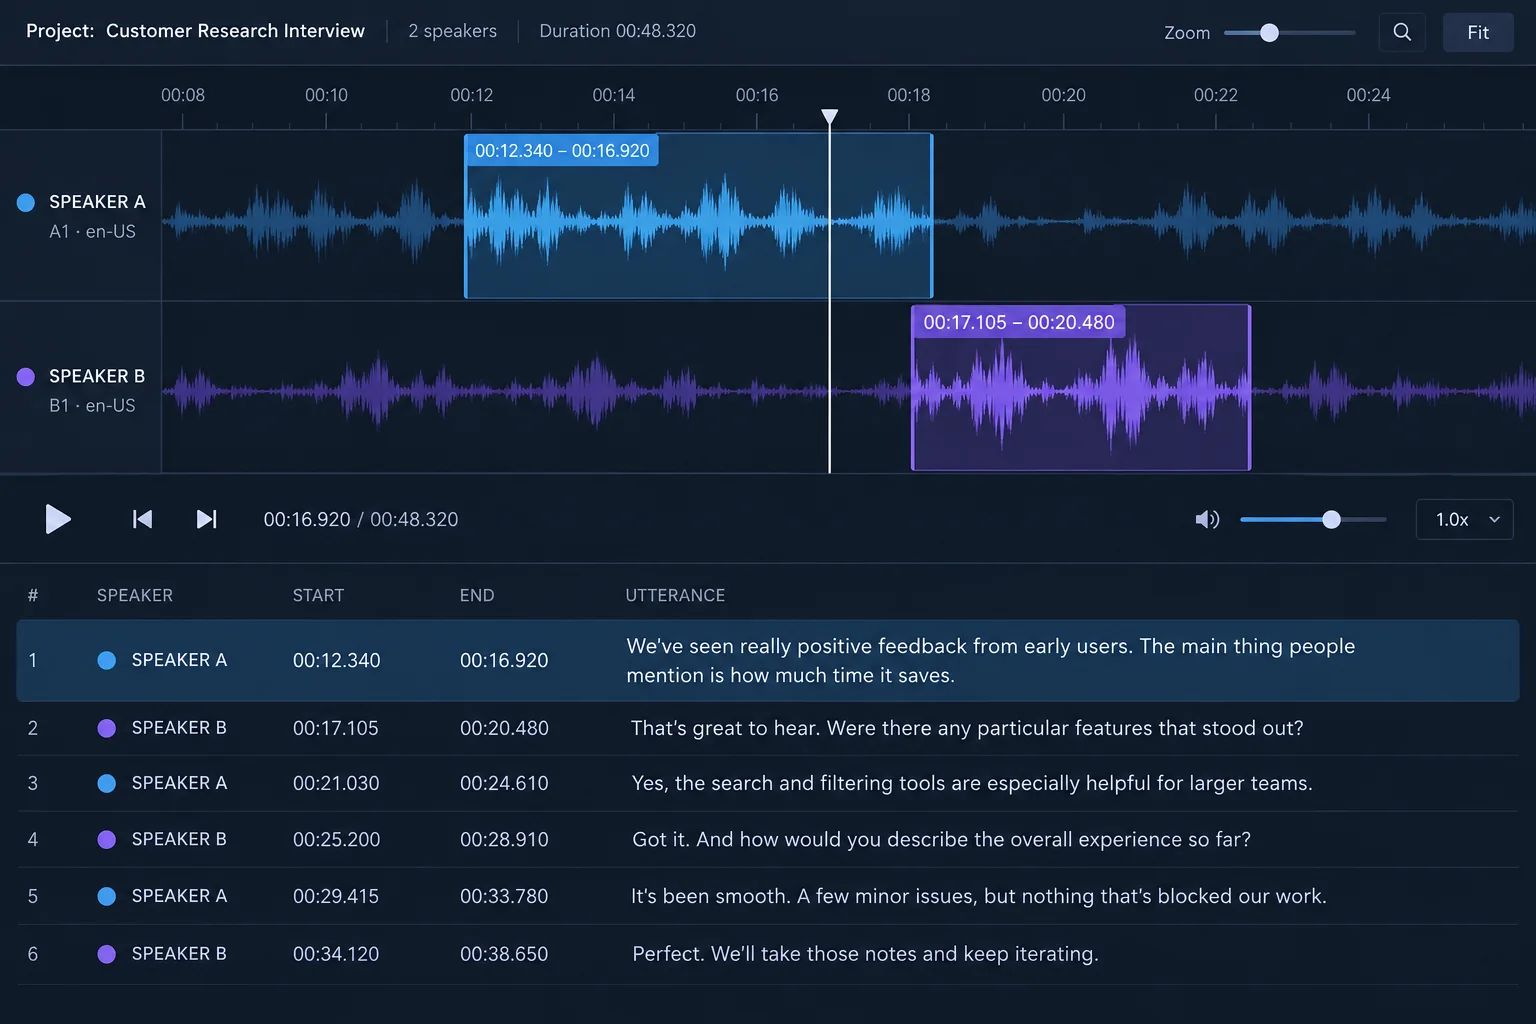
Segment-level start and end boundary logging for continuous conversational utterances, sentence boundaries, and natural speech turns across multi-speaker dialogue datasets.

Word-Level Timestamping & Forced Alignment

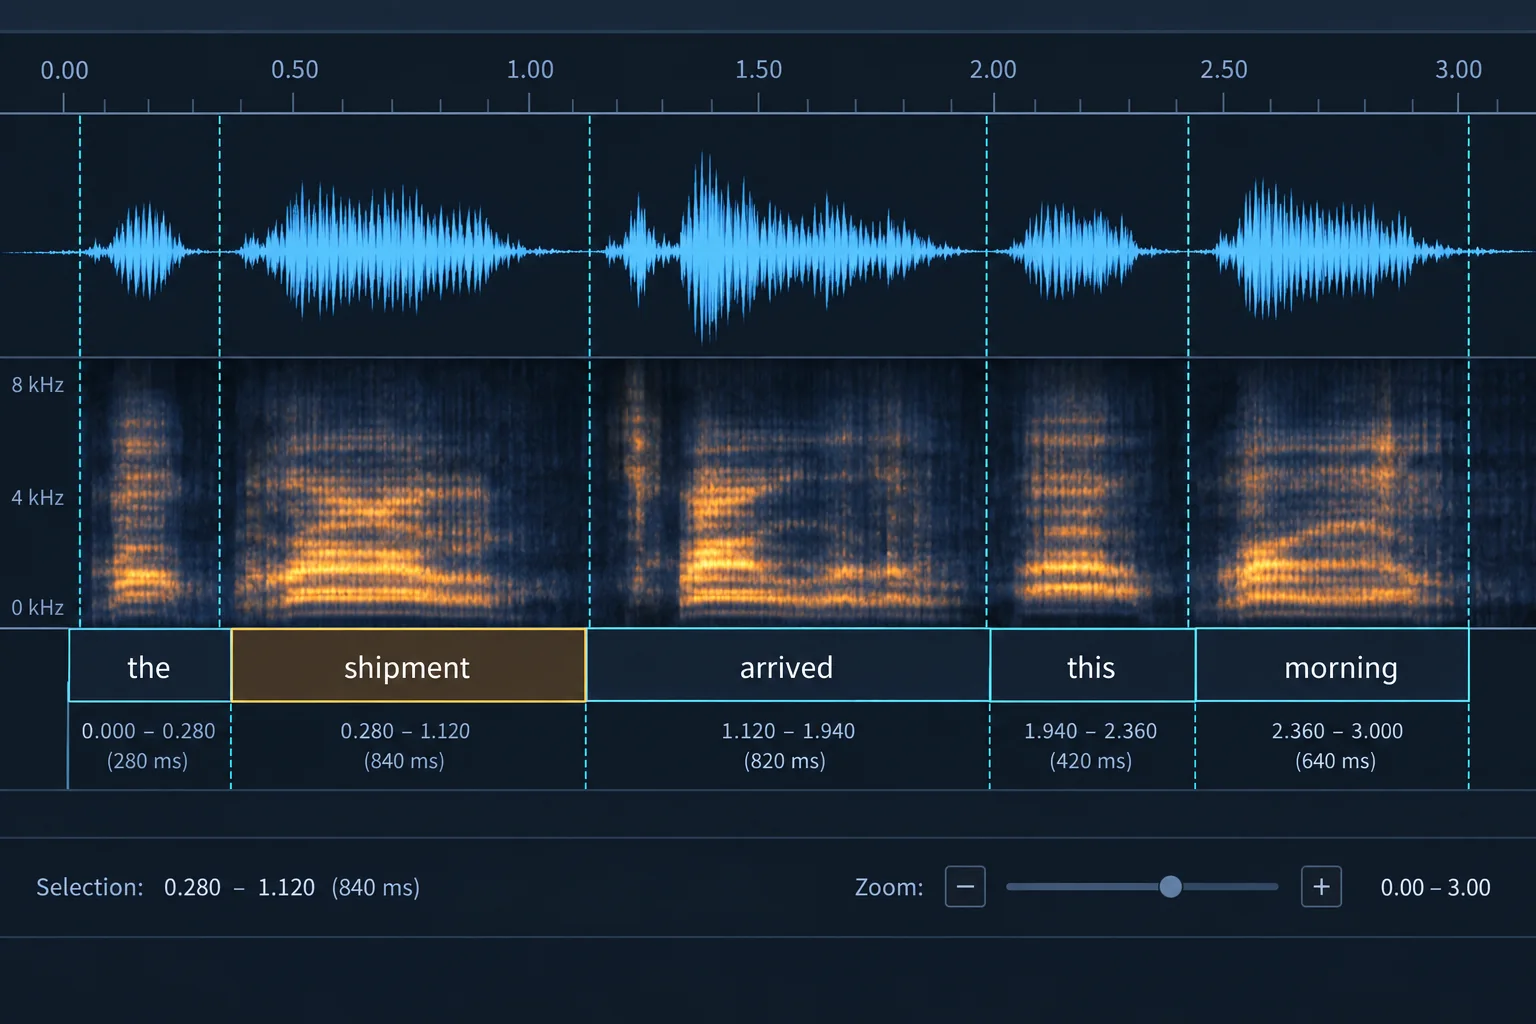
High-precision temporal alignment anchoring individual words, tokens, or sub-words to exact millisecond audio boundaries via manual correction of CTC and forced-alignment model outputs.

Acoustic Segmentation & Voice Activity Detection (VAD)

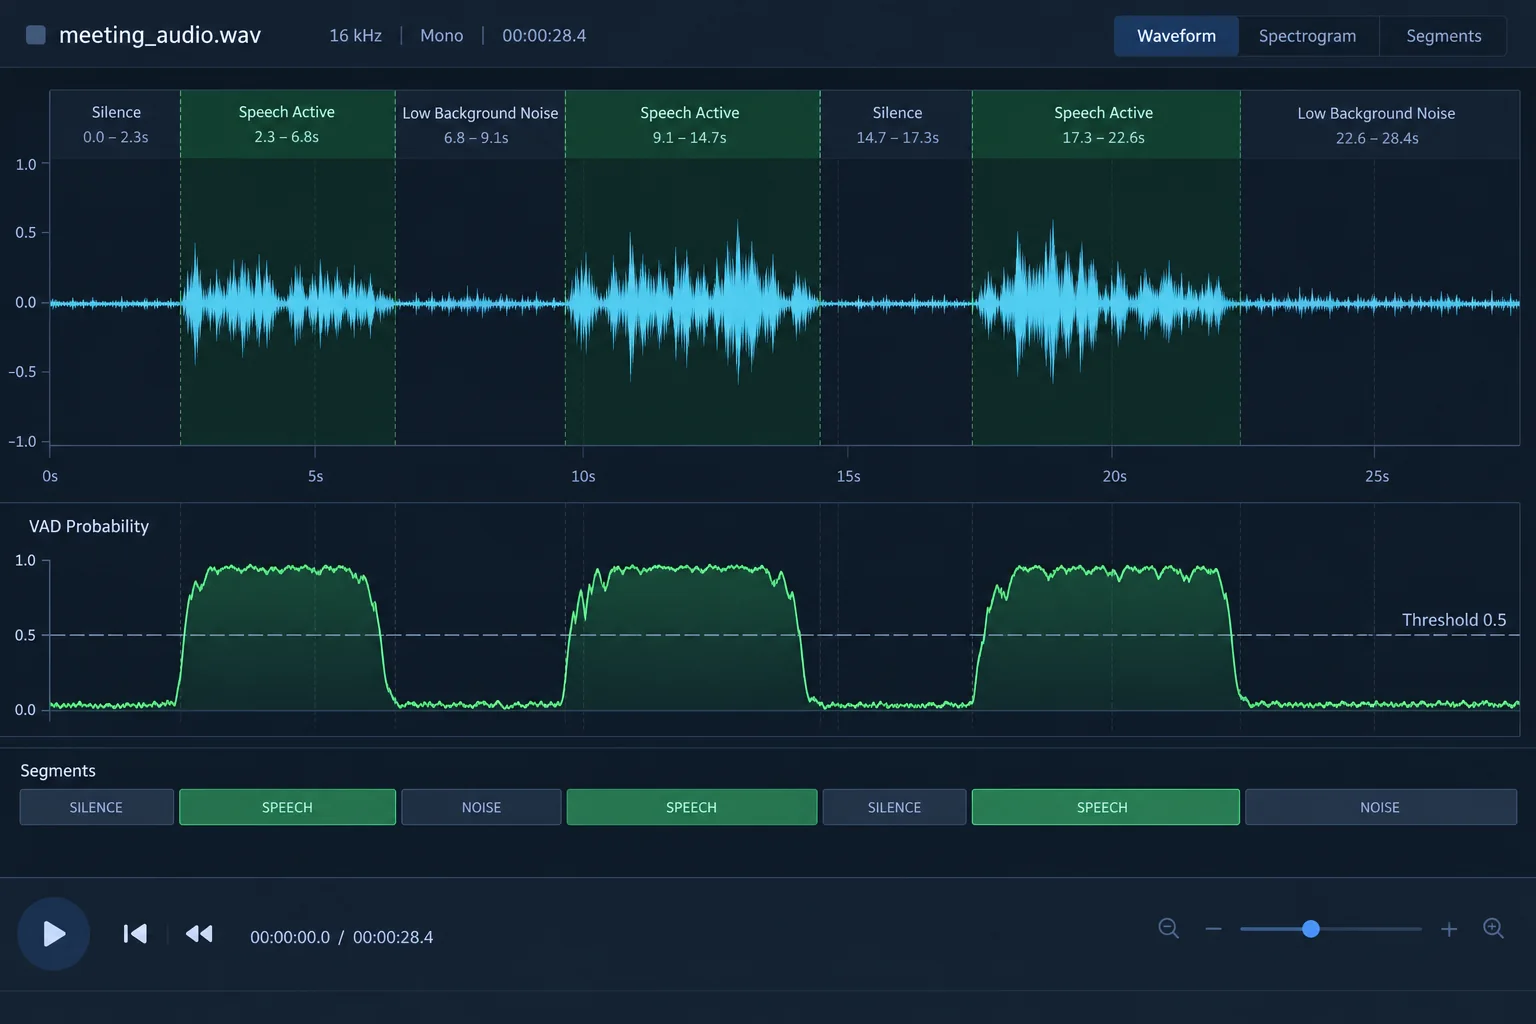
Audio stream chunking isolating active speech segments from silence, room reverberation, ambient background noise, and non-speech audio to prepare training-ready acoustic snippets.

Multilingual & Code-Switched Transcription

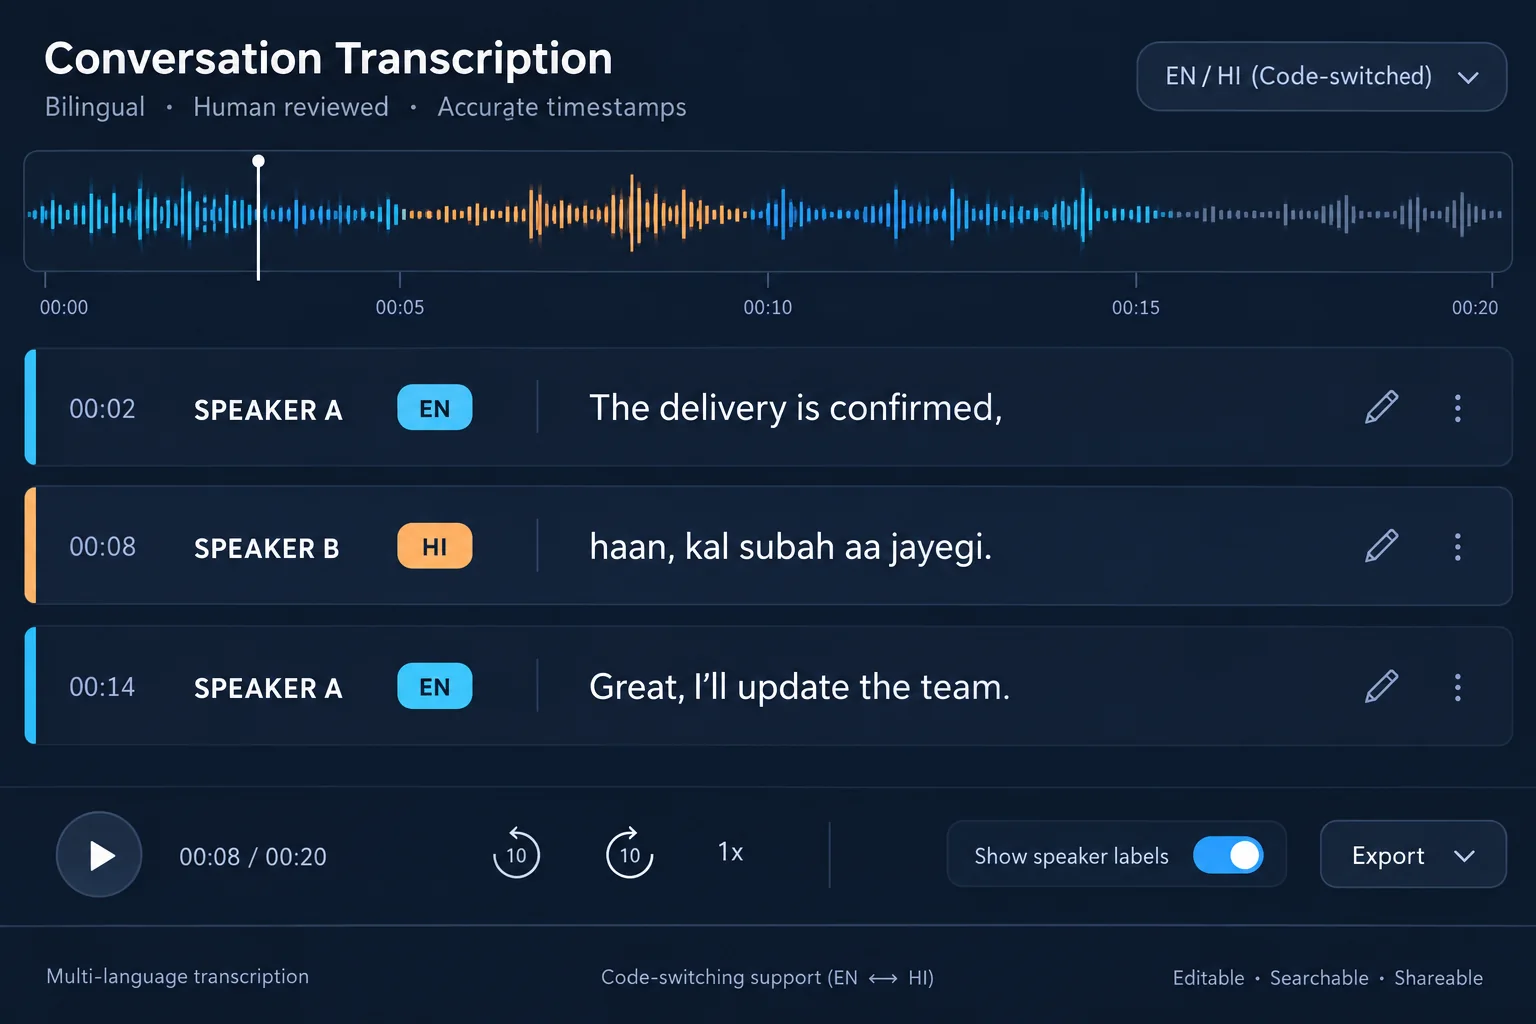
Transcription of intra-sentential and inter-sentential language switching (e.g., Spanglish, Hinglish) with language identification tagging, dialect handling, and unified script standardization.

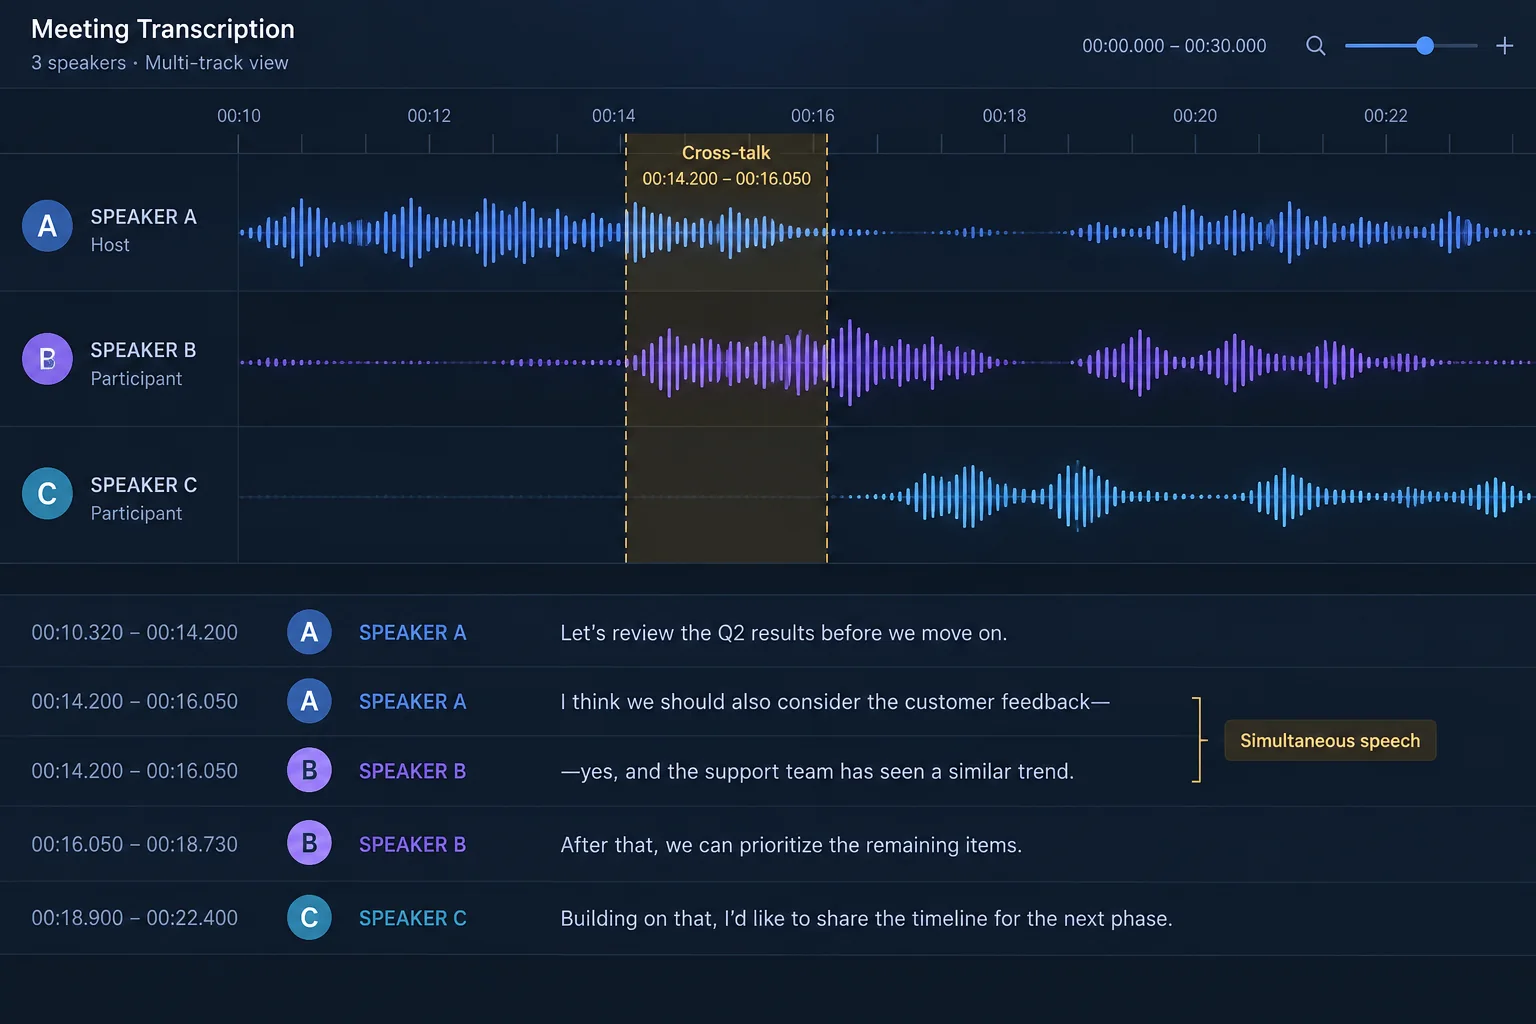
Conversational Overlap & Cross-Talk Transcription

Independent multi-track transcription and time-boundary isolation for simultaneous, overlapping speech in multi-party meetings, heated debates, and call center recordings.

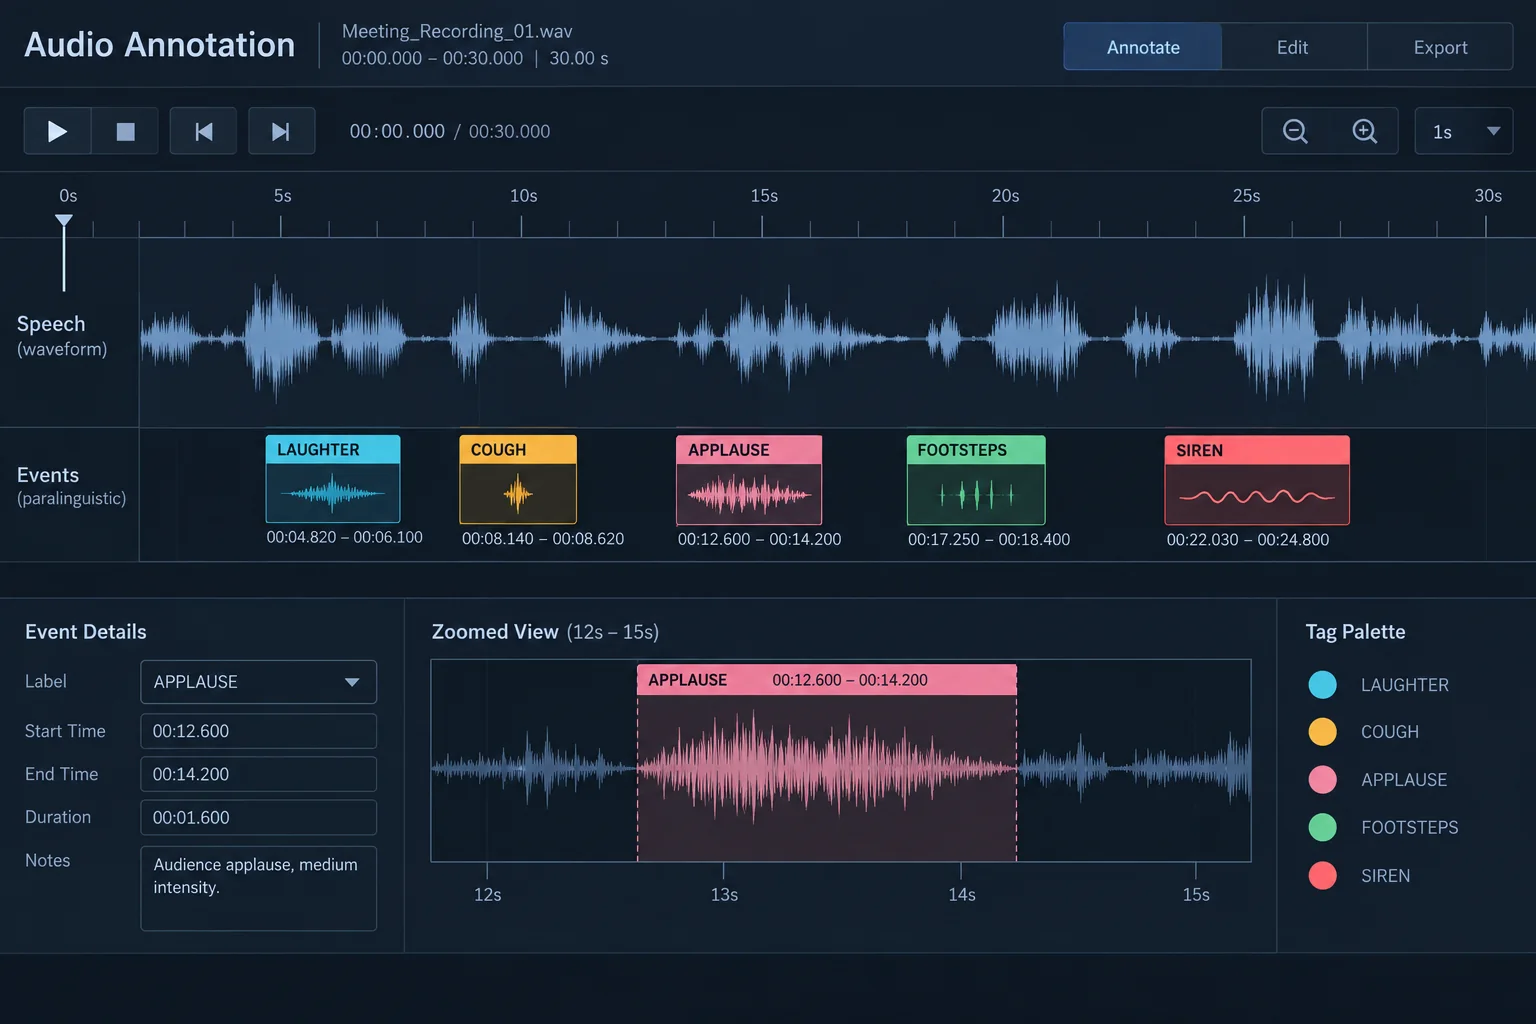
Acoustic Event & Paralinguistic Audio Tagging

Time-aligned tagging of non-verbal vocalizations (laughter, coughing, sighing, crying) and environmental sound events (applause, sirens, footsteps, music) for multimodal audio LLMs.

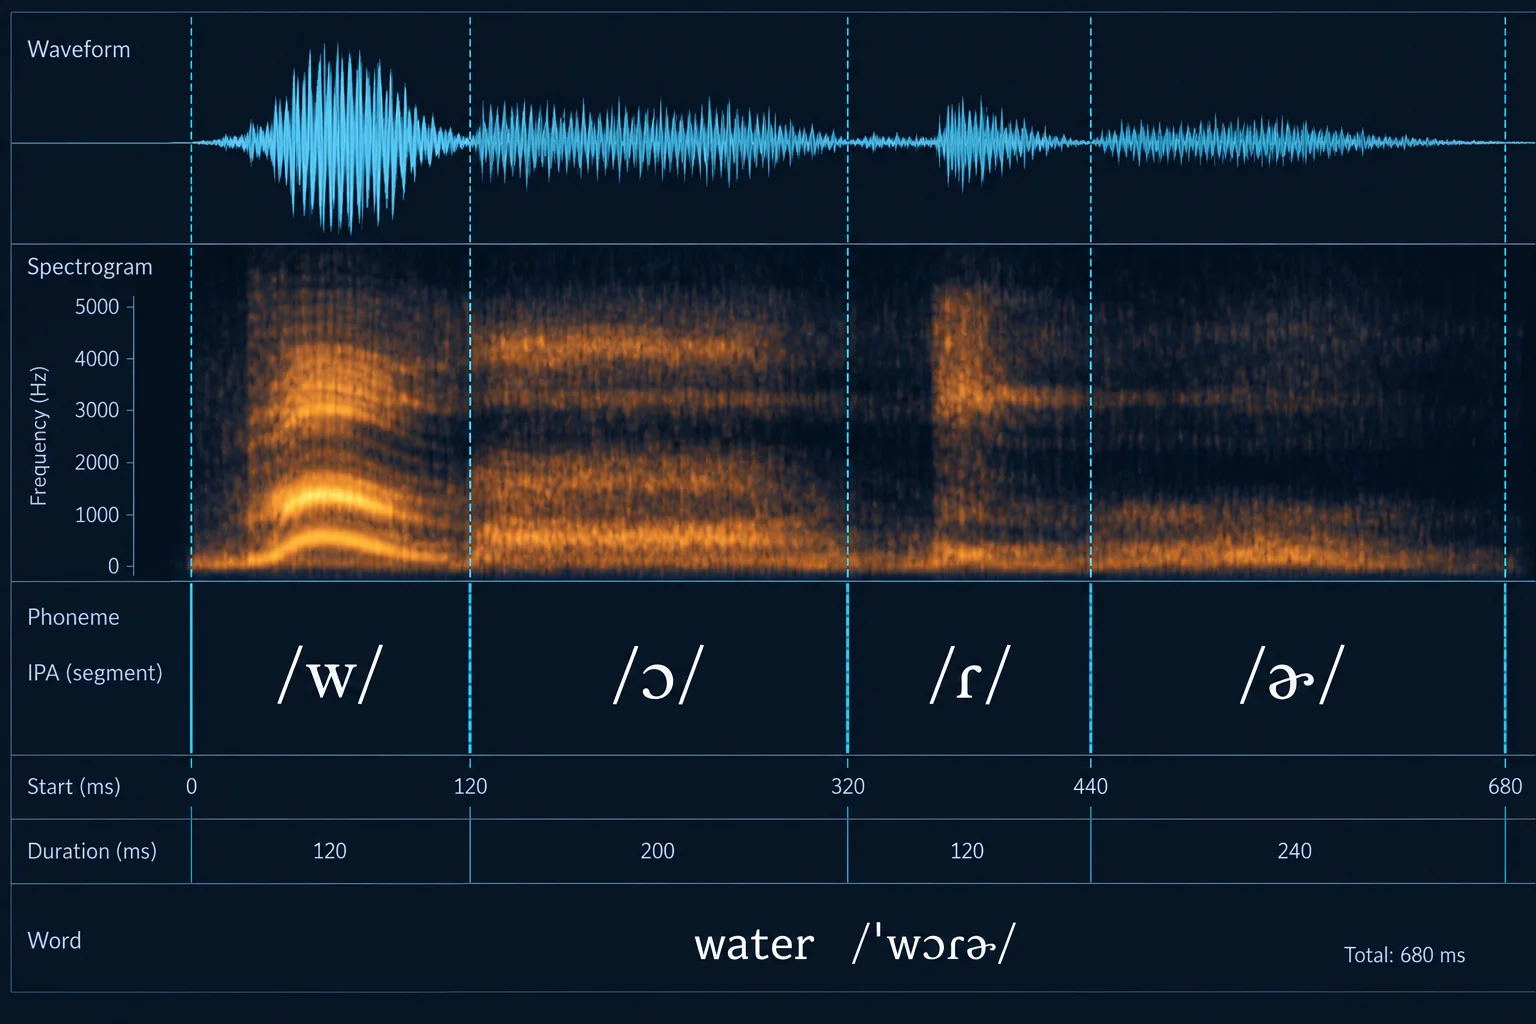
Phonetic & International Phonetic Alphabet (IPA) Transcription

Fine-grained phonetic and phonemic transcription using IPA, Arpabet, or SAMPA standards to capture regional accents, non-standard pronunciations, and dialect variations for TTS voice synthesis.

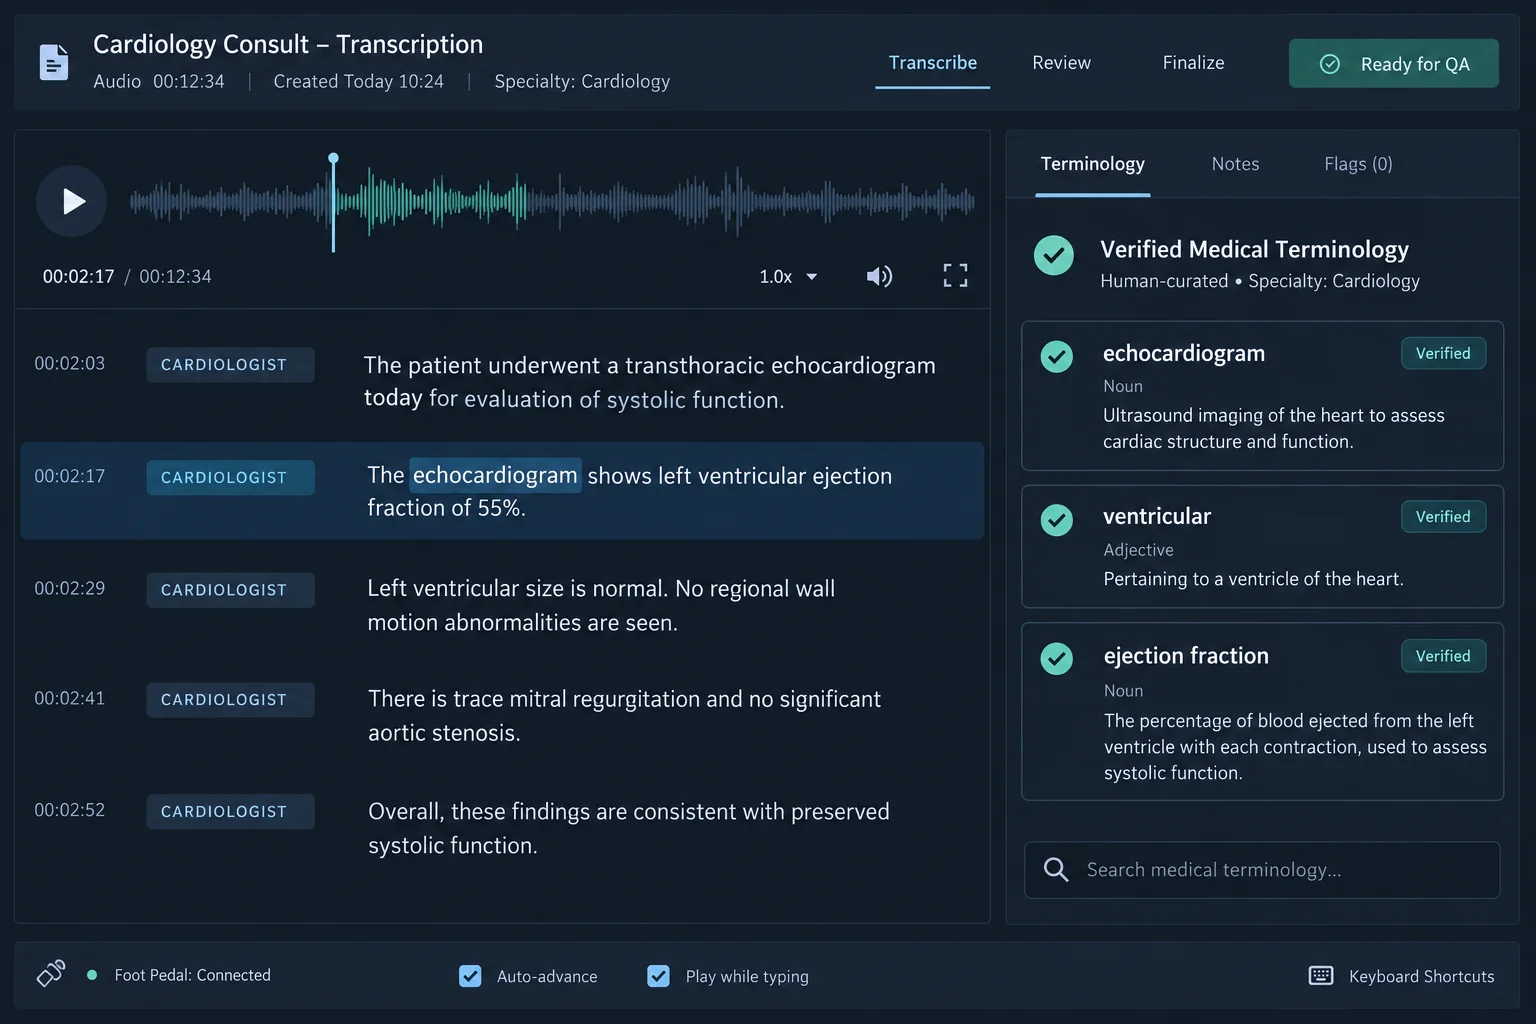
Domain-Specific Technical Lexicon Transcription

Specialized transcription adhering to strict industry nomenclatures, specialized terminologies, and custom pronunciation lexicons across clinical medicine, legal depositions, financial earnings calls, and aviation ATC.

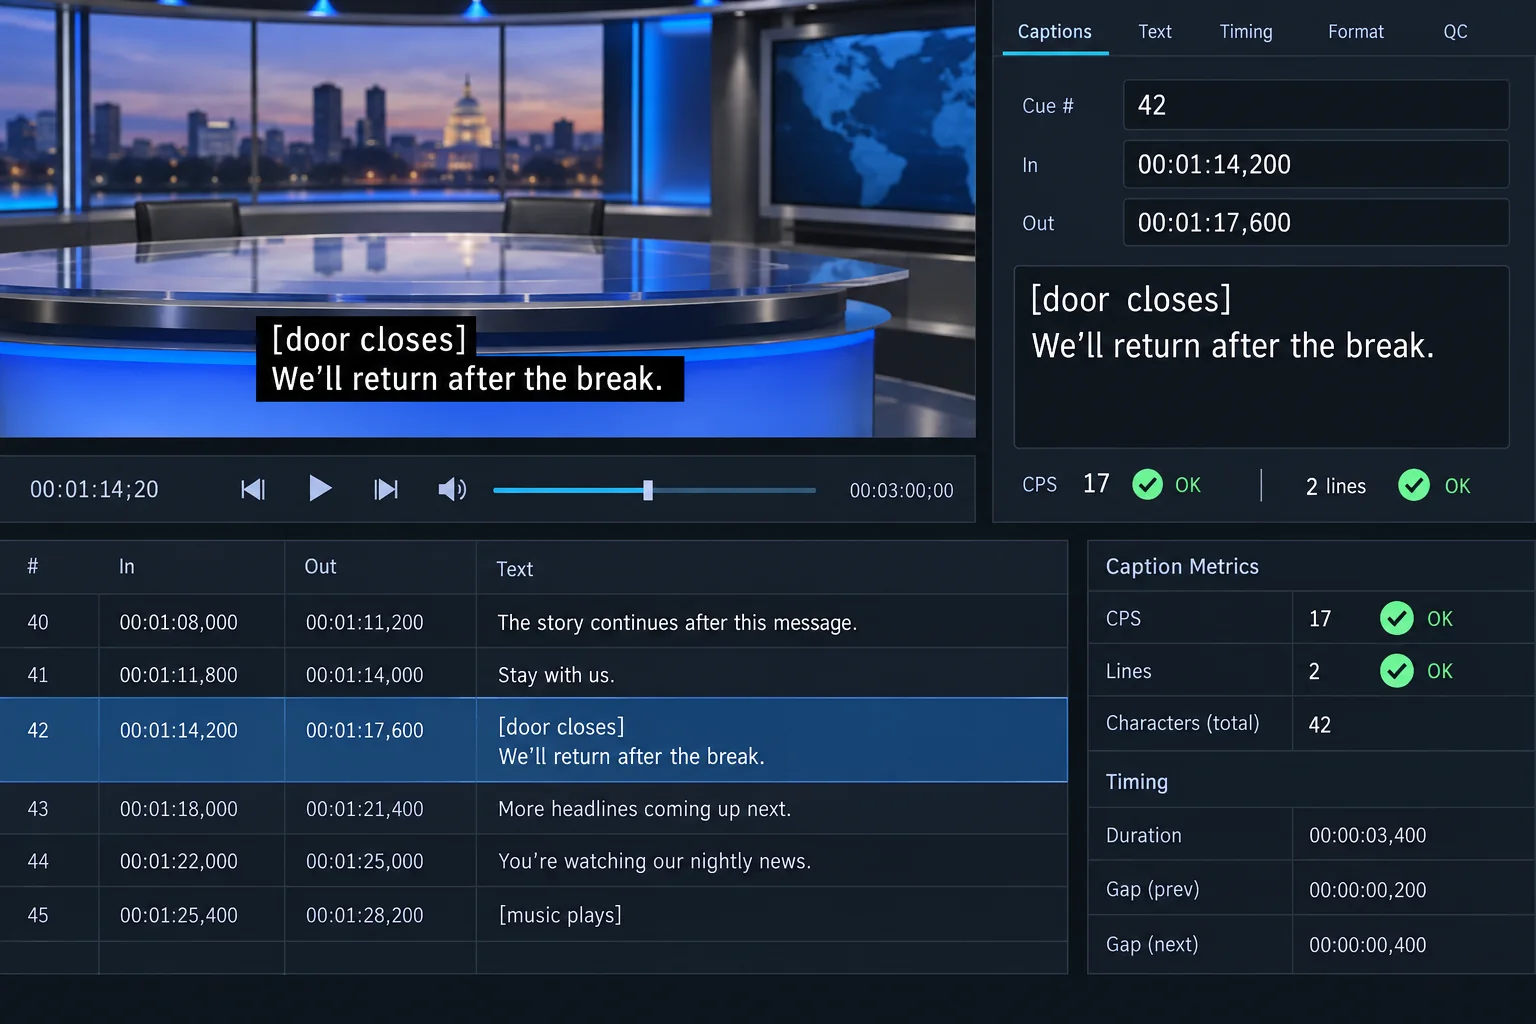
Broadcast Subtitling & Closed Captioning (SDH)

Compliant subtitle and closed caption authoring (SRT, VTT, TTML) strictly adhering to broadcast reading-speed constraints (CPS/WPM), line-length limits, and Subtitles for the Deaf and Hard of Hearing (SDH) standards.
FLEXIBLE DELIVERY

Tooling & Platform-Agnostic Execution

01

Client-Hosted Platforms

Our transcription teams can work directly inside client-approved speech annotation environments supporting waveform review, segment creation, timestamps, transcription, and QA workflows, including Label Studio, SuperAnnotate, and other approved platforms.

LABEL STUDIOSUPERANNOTATECLIENT HOSTED
02

Proprietary Client Consoles

Annotators can work inside client-owned audio platforms through approved secure access, following your existing transcription rules, timestamp format, normalization conventions, language guidelines, keyboard workflows, and review stages.

CLIENT UIVPNPOD
03

Josisoft Managed Infrastructure

When no production annotation platform is available, we can configure controlled project workspaces around your audio files, transcription schema, timestamp requirements, role permissions, and QA workflow for pilot and scaled delivery.

CONTROLLEDCONFIGUREDMANAGED
DEPLOYED CONTEXT

Real-World Transcription Applications

Conversational AI & Voice Interfaces

Timestamped transcripts and segmented speech data for conversational systems, voice interfaces, speech understanding datasets, and human-machine interaction research.

Contact Center Conversations

Customer-service recordings and call datasets transcribed with synchronized timestamps, segmentation, and project-defined formatting for conversation analysis and language-model workflows.

Media, Interviews & Research

Interviews, discussions, podcasts, field recordings, research audio, and recorded media converted into synchronized structured transcripts for downstream processing.

Multilingual Speech Datasets

Audio datasets transcribed across multiple languages, regional variations, accents, and code-switched conversations using client-defined script, transliteration, and normalization rules.

CONTROLLED OPERATIONS

Security, Compliance & Workforce Governance

01

Mandatory Bilateral NDAs

Every annotator, QA reviewer, and project manager signs an NDA before accessing project assets.

02

Security & Clean-Room Training

Personnel are trained on data confidentiality: strict restrictions on screen sharing, zero tolerance for screen recording or screenshots, and supervised session management.

03

Governed Physical Delivery Hub

On-premise operations at our central Durgapur facility enforce controlled local networks, restricted USB and removable media ports, and supervised work environments.

04

Isolated Hybrid Pods

Each client is assigned a dedicated team working in siloed environments, preventing cross-project data contamination and maintaining domain context.

START A PROJECT

Start With a Calibrated Transcription Pilot.

Share a representative audio sample, target language, transcription guidelines, segmentation rules, timestamp requirements, and QA criteria with our delivery team. We will calibrate the workflow, complete a controlled pilot batch, review timing and linguistic edge cases, and return the sample for acceptance before production scaling.

Request a Pilot Batch