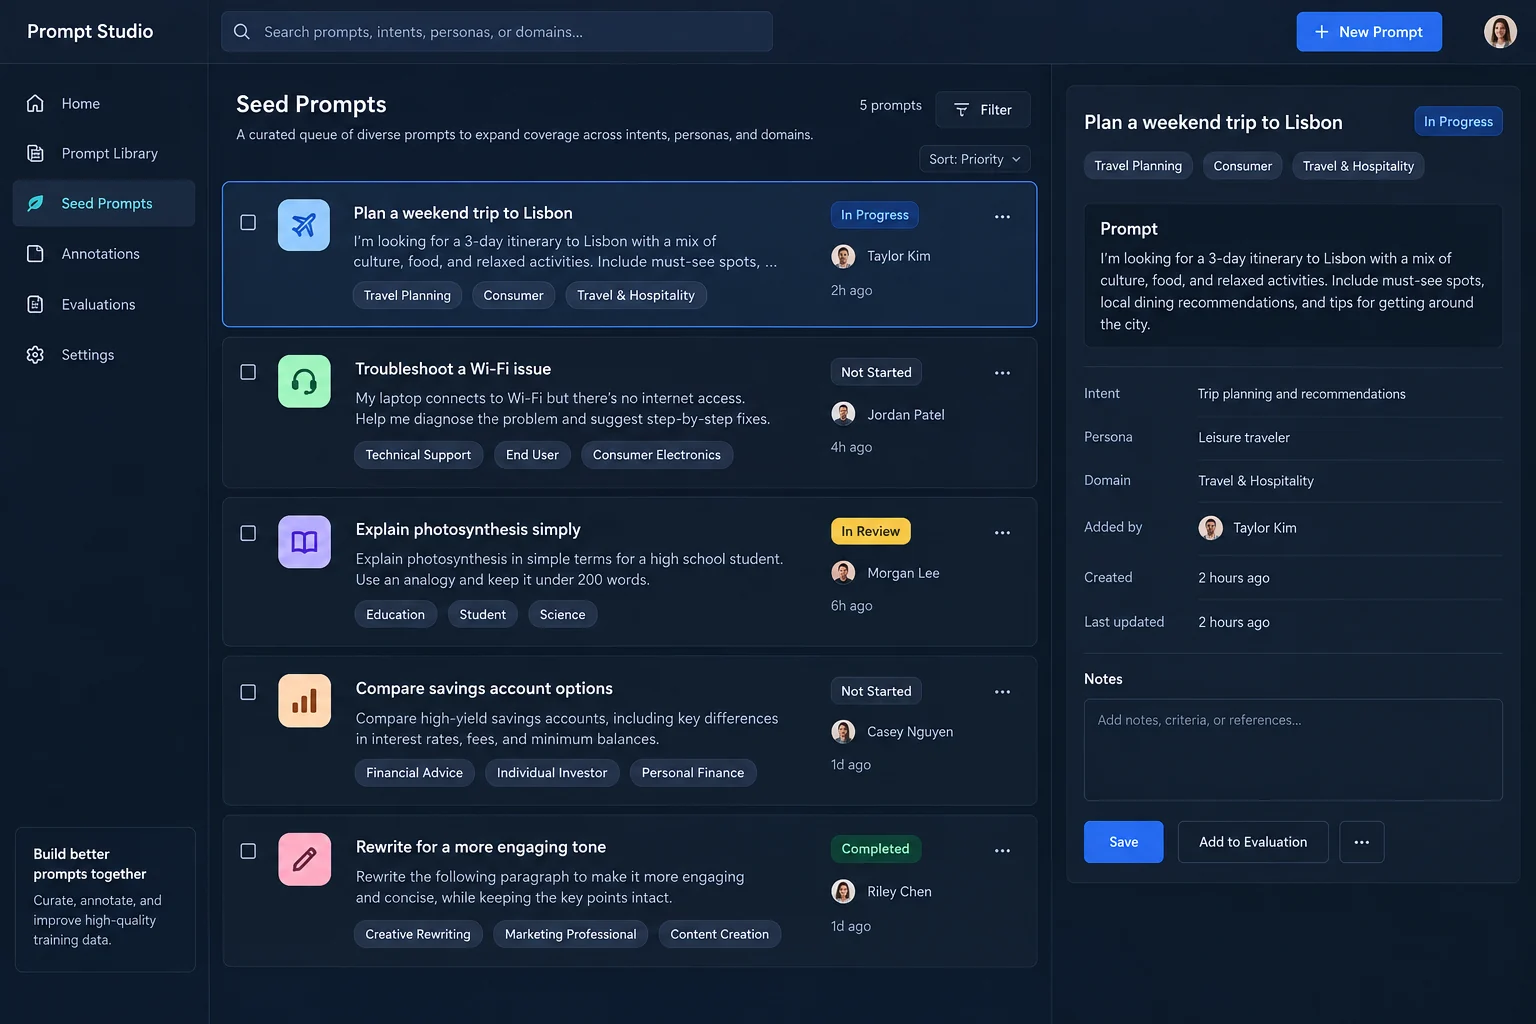
Open-Ended Seed Prompt Authoring
Authoring authentic, diverse user prompts across thousands of distinct intents, conversational personas, and domain topics to build broad foundational instruction coverage without synthetic repetition.
Josisoft creates custom prompt and response datasets tailored to your domain requirements, task complexity, and tone guidelines—delivering the diverse, high-quality training pairs required to improve model accuracy and eliminate repetitive outputs.
Talk to a Data Specialist“Summarize the following support ticket in two sentences and identify the primary issue.”
The customer’s replacement device cannot complete activation after account verification, despite two restart attempts. The primary issue is a device activation failure that requires account-provisioning validation.
RESPONSE · 31 WORDS · TWO SENTENCESAuthoring authentic, diverse user prompts across thousands of distinct intents, conversational personas, and domain topics to build broad foundational instruction coverage without synthetic repetition.

Designing complex prompts embedded with specific operational rules—including negative constraints, length limits, required formats, and multi-part instructions—to train and test strict instruction following.
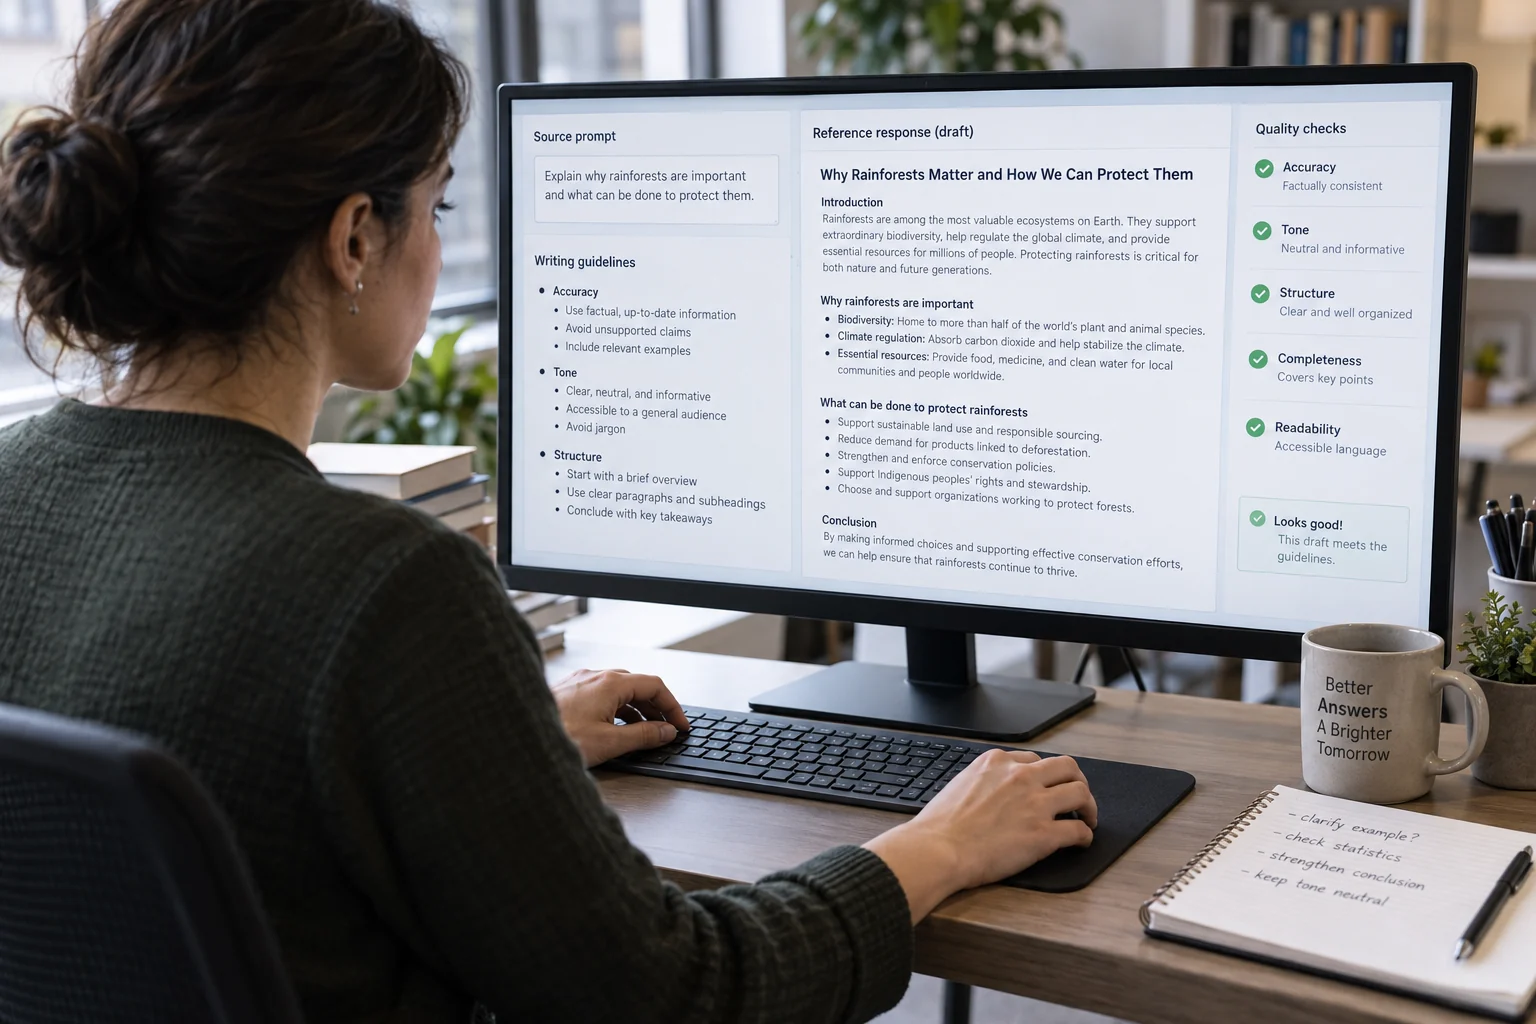
End-to-end authoring of comprehensive, publication-grade reference responses written from scratch by human linguists and subject specialists according to client guidelines for accuracy, tone, and structure.
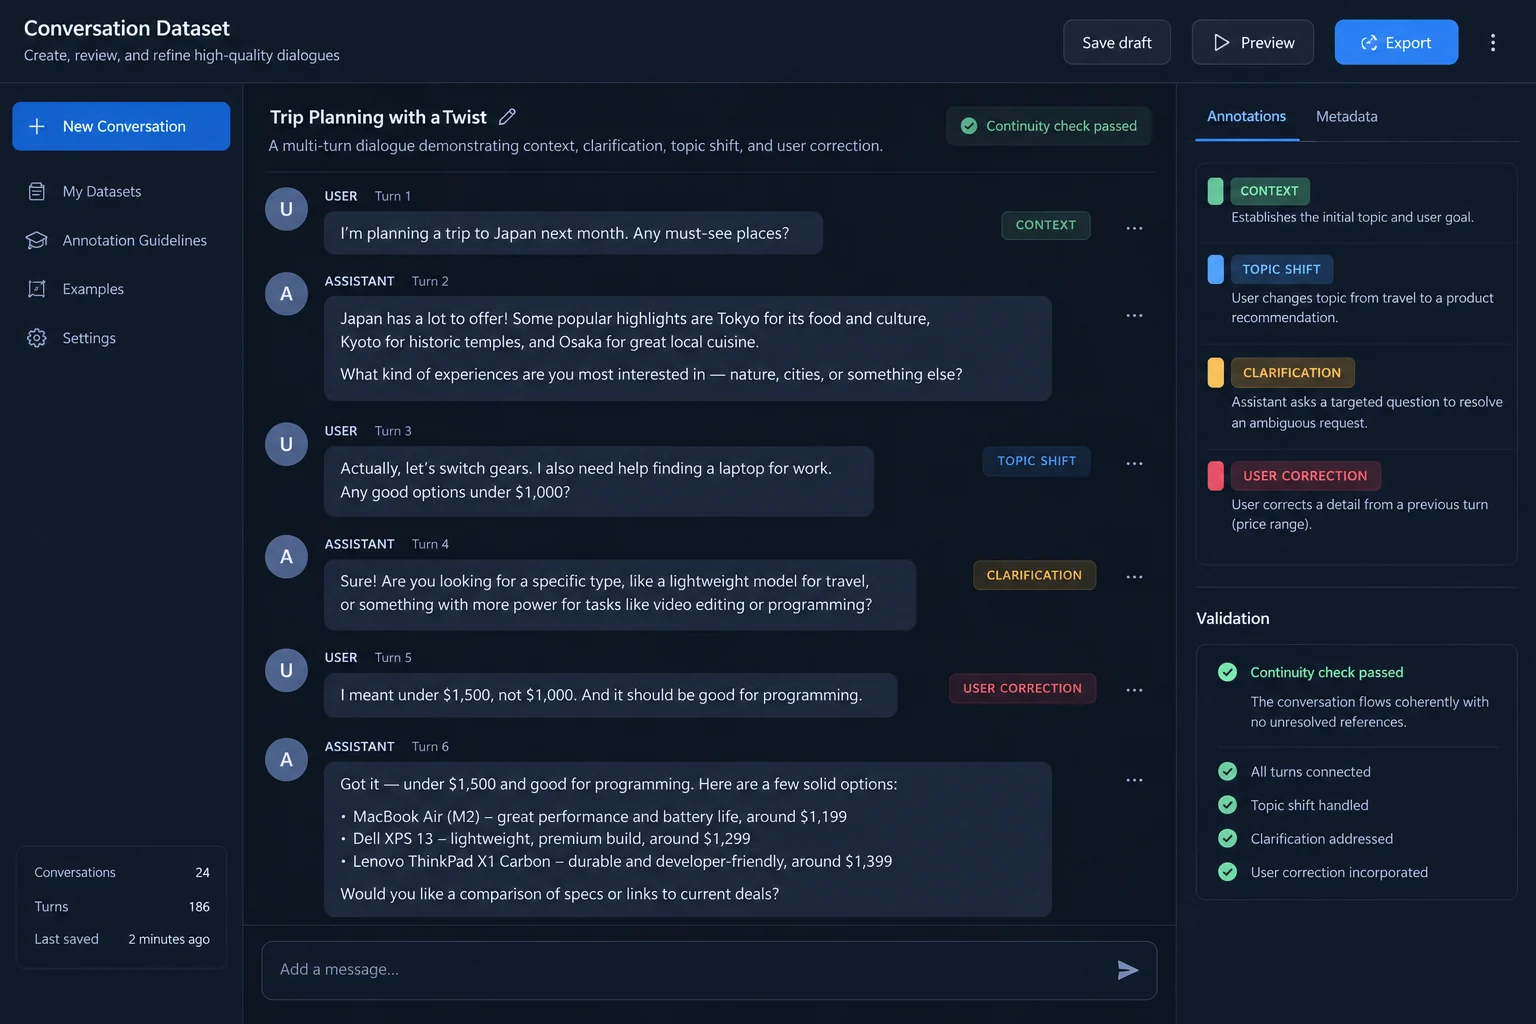
Developing multi-turn dialogue scripts and realistic conversation flows—including contextual follow-ups, topic shifts, ambiguous user requests, and mid-dialogue corrections—for conversational agents.
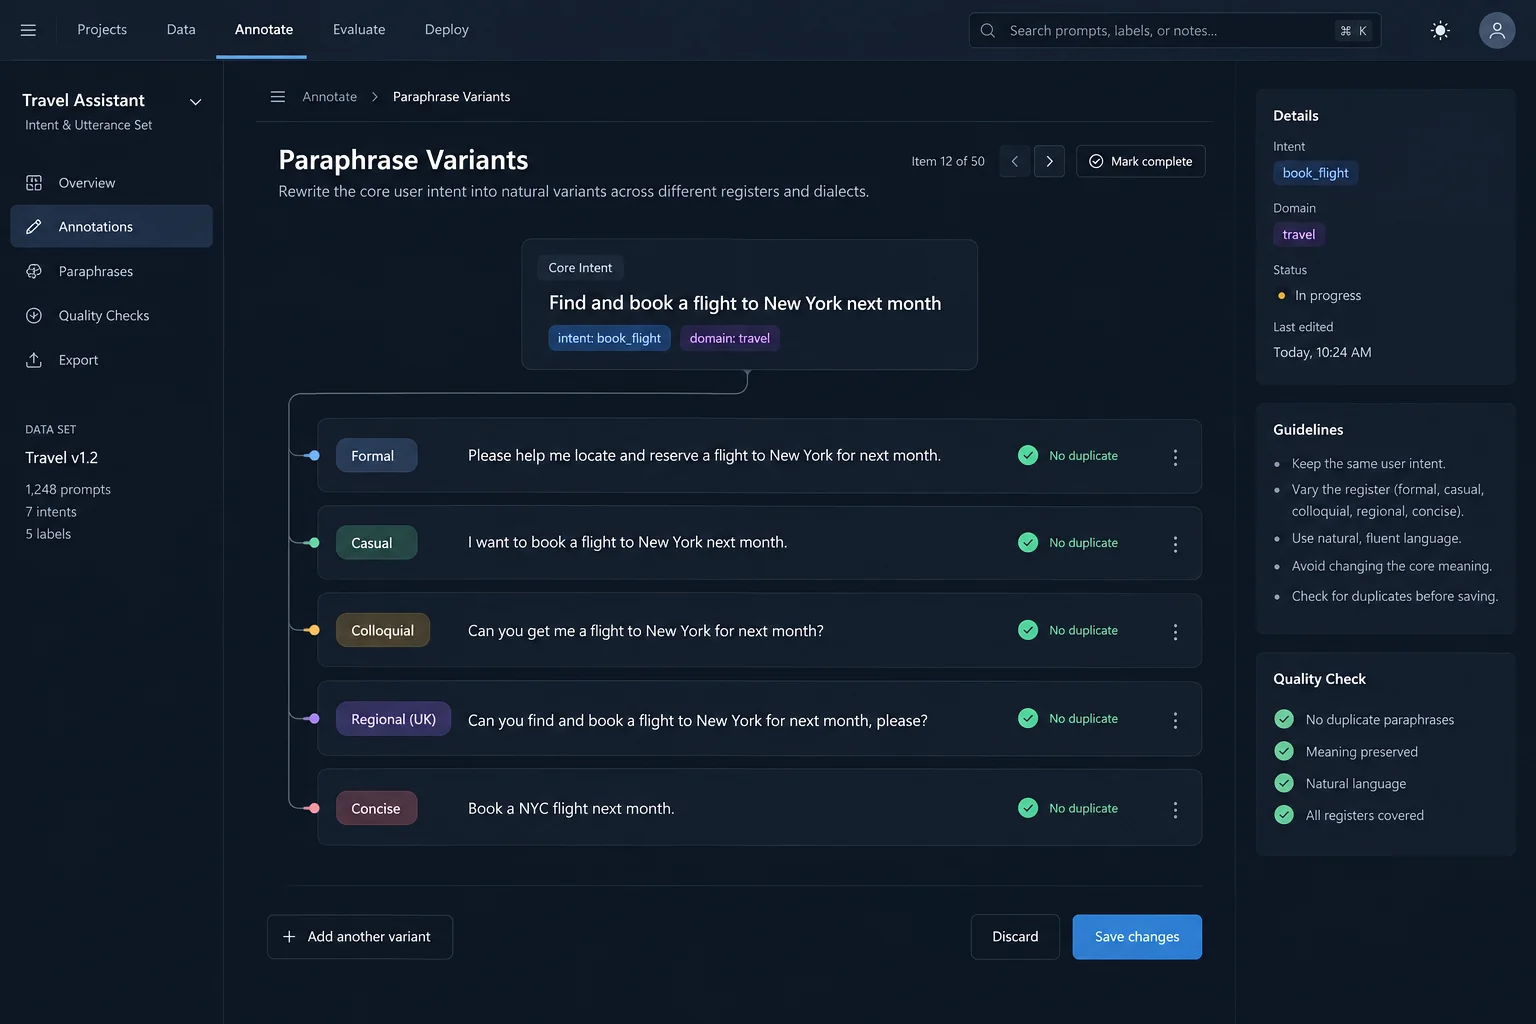
Systematic human rewriting of core prompt intents across varied dialects, registers, colloquialisms, and sentence structures to make models robust against different user phrasing styles.

Authoring multiple distinct, high-quality response variations (varying in style, length, or structural layout) for identical prompts to generate diverse candidate pools for preference and ranking pipelines.
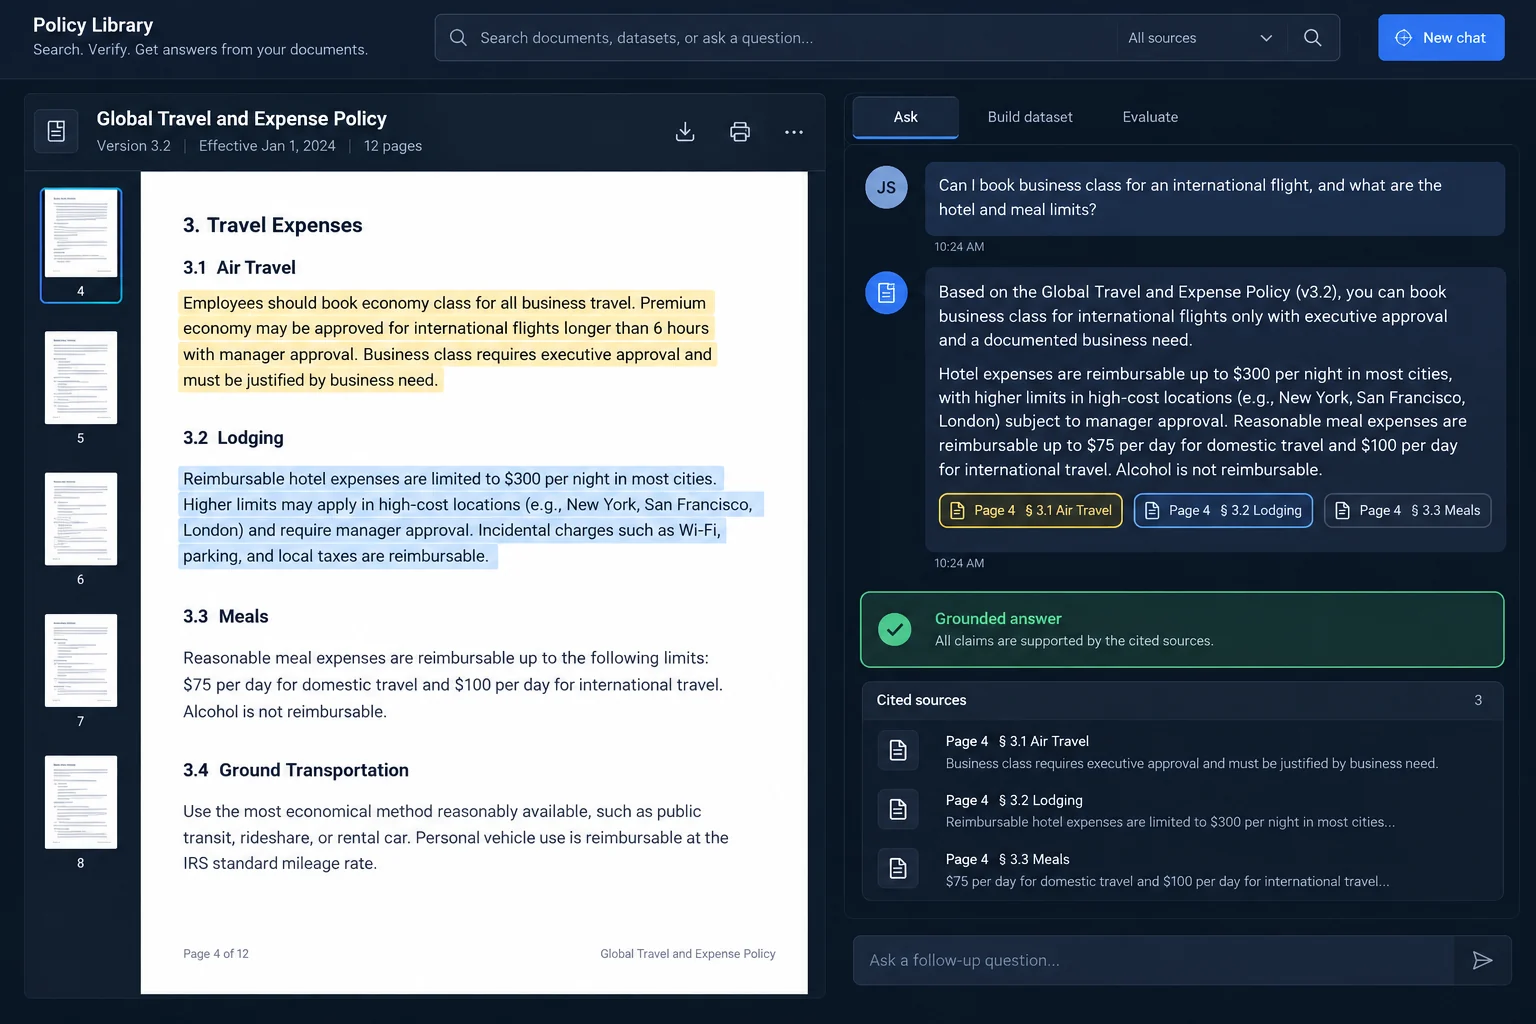
Drafting realistic user queries paired with authoritative, hallucination-free answers derived strictly from provided enterprise documents, technical manuals, or knowledge bases, complete with exact source citations.

Authoring advanced prompts and verified solutions executed by credentialed specialists across software engineering, quantitative finance, corporate law, and clinical medicine.
Our evaluators can work directly inside client-approved environments supporting prompt display, response review, rubric scoring, issue tagging, reviewer notes, and QA workflows.
Reviewers can operate within client-owned evaluation systems through approved secure access, following your prompt taxonomy, scoring dimensions, response criteria, failure labels, reviewer instructions, and review stages.
When no production evaluation interface is available, we can configure controlled project workspaces around your prompt sets, model responses, scoring rubric, issue taxonomy, reviewer roles, and QA/adjudication stages.
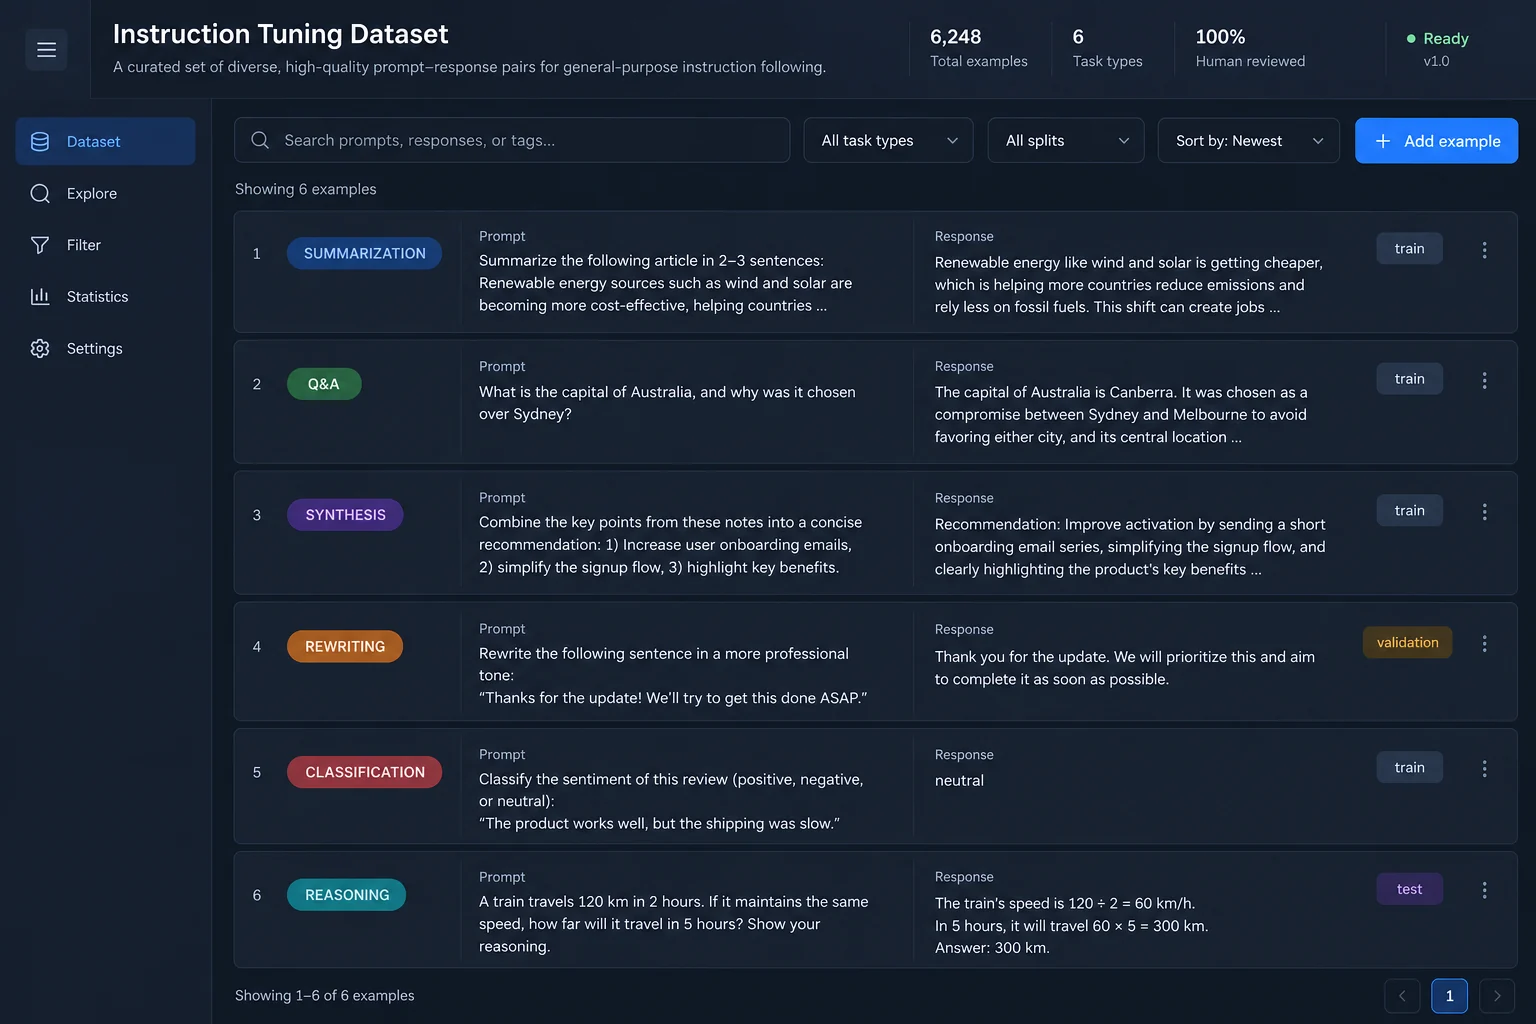
Powering core language model training with diverse prompt-response pairs across summarization, open Q&A, synthesis, creative rewriting, classification, and multi-step reasoning.

Building multi-turn dialogue datasets designed to teach chat models natural conversation flow, brand-aligned personas, handling ambiguous follow-ups, and graceful recovery from user corrections.
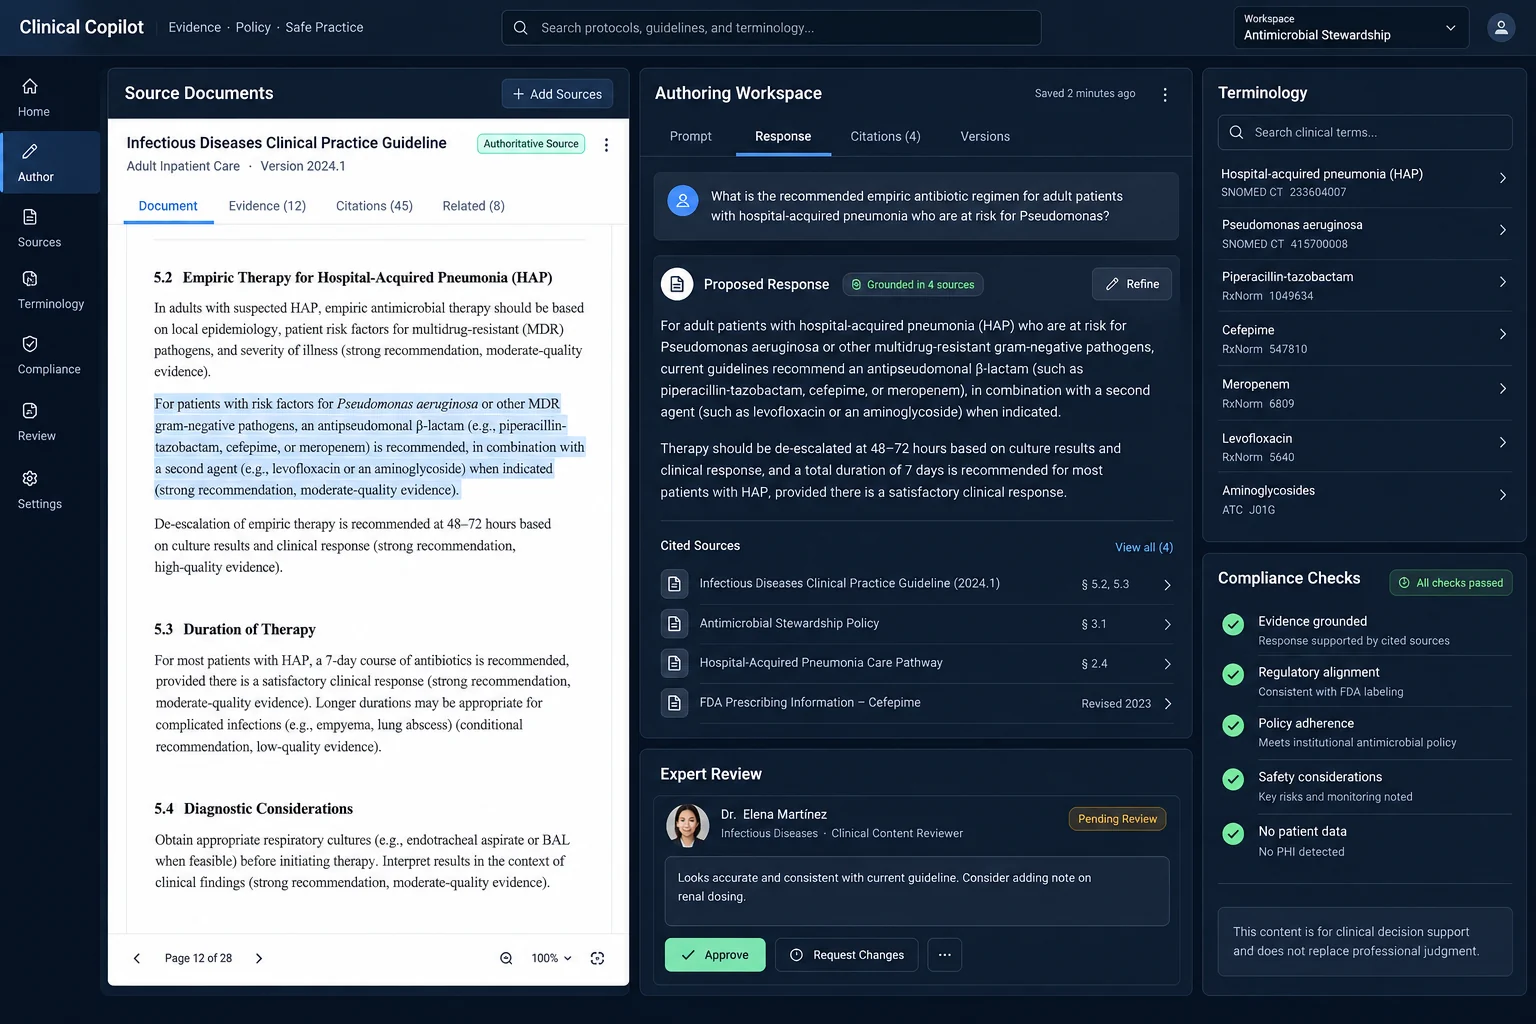
Supplying domain-grounded prompt and reference response pairs incorporating specialized vertical terminology, regulatory constraints, and proprietary documentation across healthcare, legal, finance, and technical support.
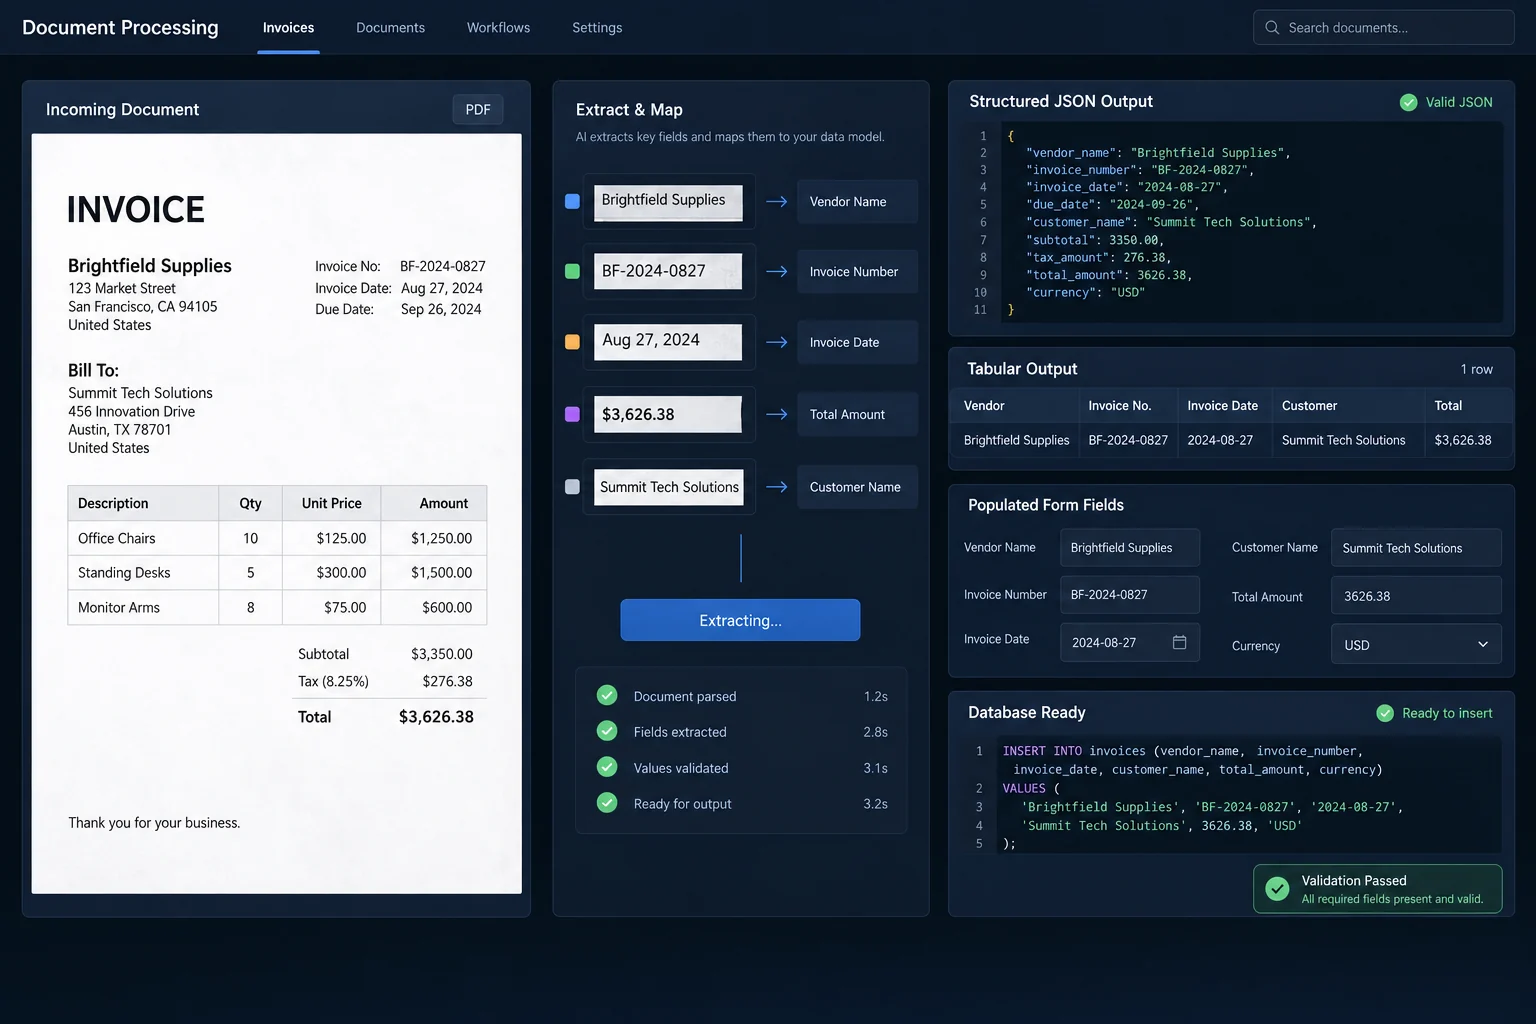
Generating targeted input-output pairs that train models to extract business data, execute form completions, query structured databases, and return clean, machine-readable formats like JSON or tables.
Every annotator, QA reviewer, and project manager signs an NDA before accessing project assets.
Personnel are trained on data confidentiality: strict restrictions on screen sharing, zero tolerance for screen recording or screenshots, and supervised session management.
On-premise operations at our central Durgapur facility enforce controlled local networks, restricted USB and removable media ports, and supervised work environments.
Each client is assigned a dedicated team working in siloed environments, preventing cross-project data contamination and maintaining domain context.
Share a representative prompt set, model responses, scoring rubric, failure taxonomy, and acceptance criteria with our delivery team. We will calibrate evaluator decisions, complete a controlled pilot batch, review disagreement and difficult cases, and return the evaluation sample for acceptance before production scaling.