Seasonal demand changes the quantity and timing of customer purchases. Inventory plans must anticipate those patterns so stock is available before demand rises without leaving excess inventory after the season ends.
RLHF
Human Preference Data for Better Model Behavior.
RLHF depends on more than collecting simple thumbs-up or thumbs-down decisions. Reviewers must interpret instructions, compare competing outputs, apply consistent preference criteria, distinguish subtle quality differences, and resolve ambiguous cases. Josisoft builds human-feedback workflows around your evaluation rubric, response pairs, ranking protocol, safety criteria, and QA process so preference data remains consistent from evaluator calibration through production delivery.
Talk to a Data SpecialistPROMPT
“Explain why seasonal demand can affect inventory planning.”
Seasonal changes affect inventory because customers buy different products throughout the year. Businesses should update stock when seasons change.
PREFERENCE STRENGTH
A MUCH BETTERA BETTERTIEB BETTERB MUCH BETTER
REVIEWER NOTE
A explains both pre-season availability and post-season overstock risk.
QUALITY FLAGSNONE
FINAL DECISIONRESPONSE A
Core RLHF Capabilities

Pairwise Response Ranking
Side-by-side (A vs. B) evaluation of competing model outputs against the same prompt, selecting the superior response based on task adherence, helpfulness, and accuracy.

Multi-Response Ranking
Ordinal ranking of three or more candidate responses from strongest to weakest across structured quality criteria to provide multi-tier preference distributions for reward modeling.

Rubric-Based Multi-Dimensional Scoring
Independent criteria scoring grading individual completions across separate quality axes, including factual accuracy, instruction following, clarity, tone, and conciseness.
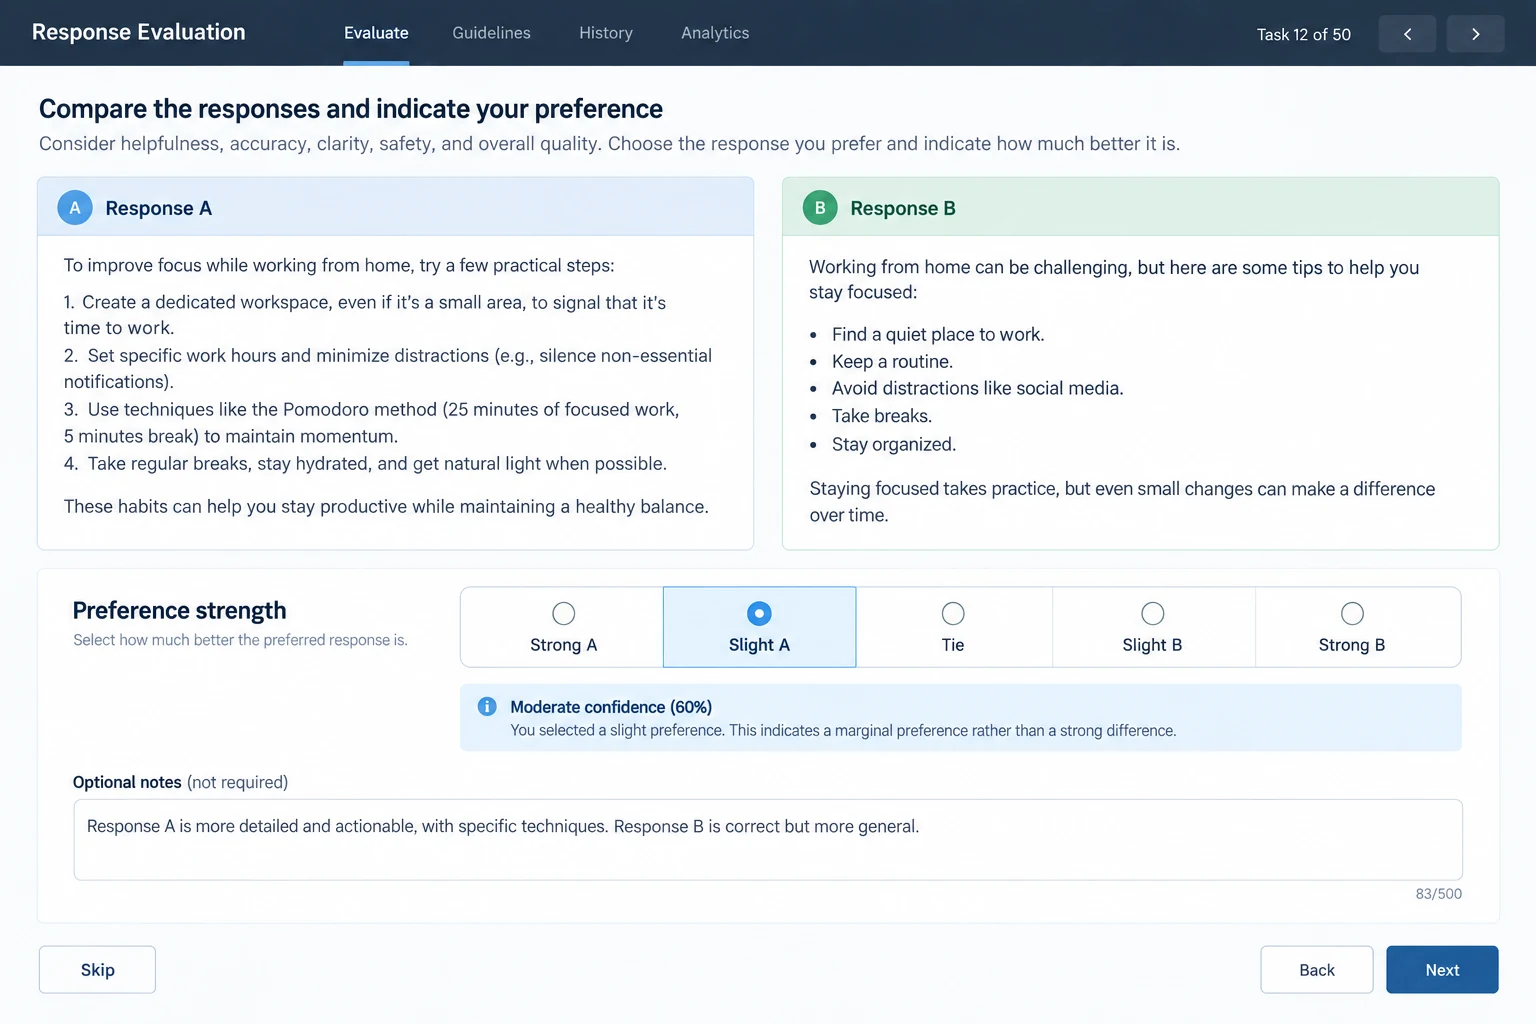
Preference Strength & Margin Grading
Calibrated margin assessment capturing the degree of preference between outputs (e.g., slight preference, strong preference, or acceptable tie) to separate marginal differences from clear quality gaps.

Preference Critique & Rationale Generation
Detailed written justifications authored by evaluators explaining the explicit reasoning errors, factual gaps, or stylistic advantages that determined the ranking decision.

Response Rewriting & Error Correction
Expert human editing of rejected or lower-ranked candidate responses, fixing hallucinations and formatting flaws to turn flawed outputs into ideal reference demonstrations.

Safety & Refusal Preference Alignment
Evaluation of candidate responses to sensitive, adversarial, or borderline prompts, training models to balance polite, necessary safety refusals against unhelpful over-refusals.
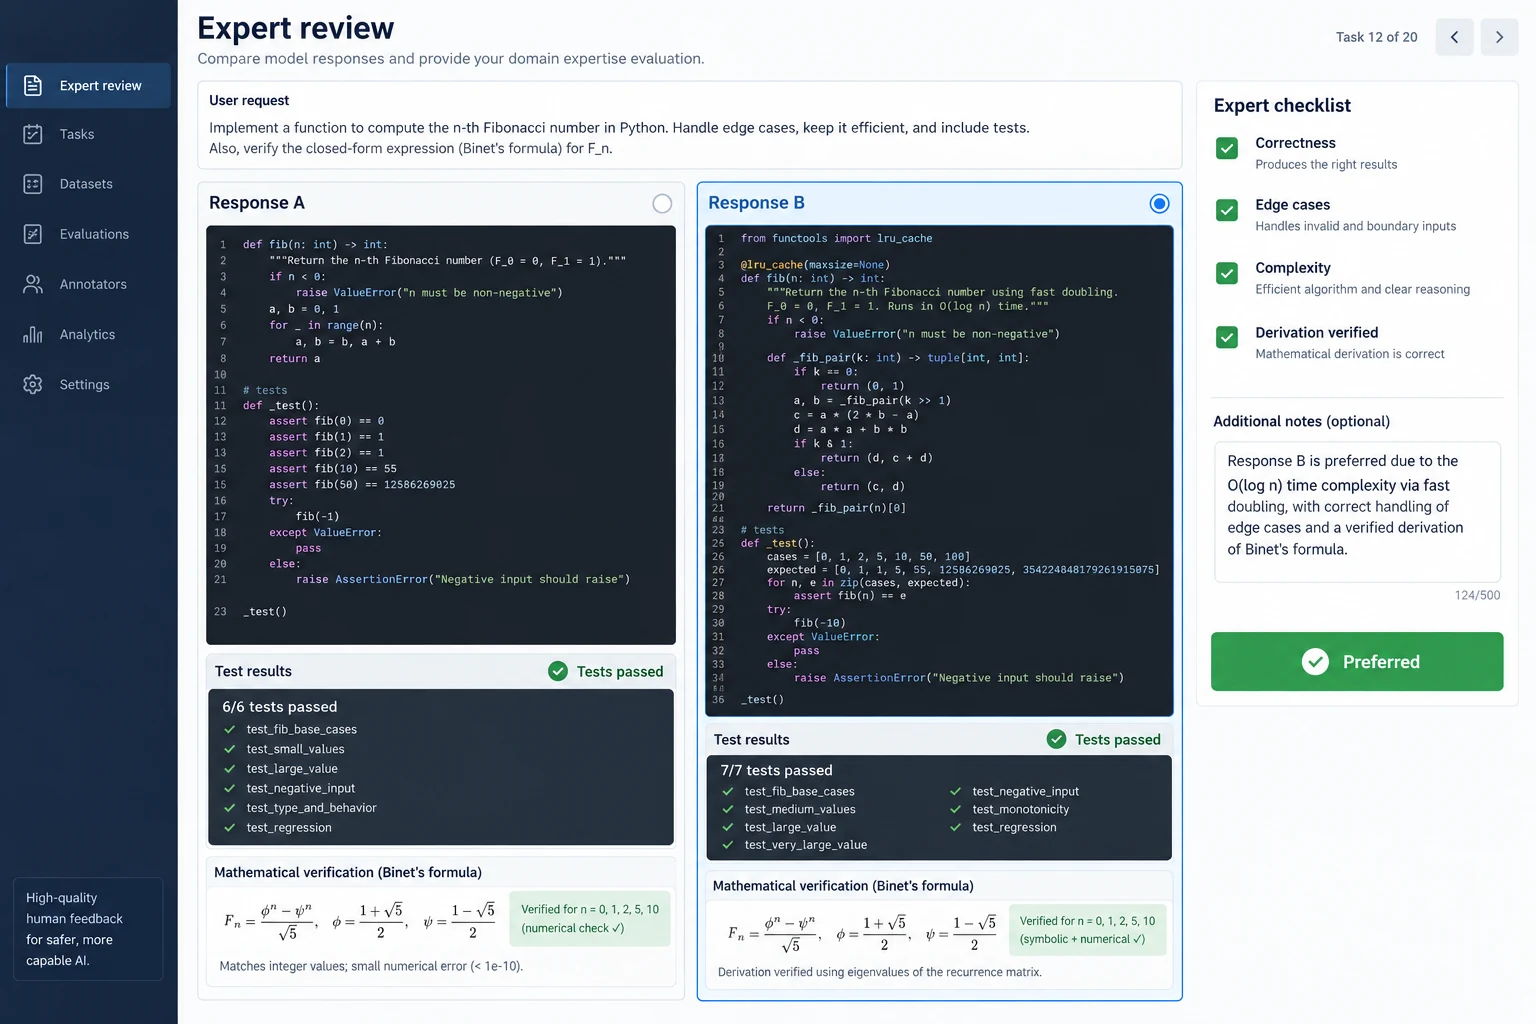
Domain-Expert Preference Evaluation
High-complexity preference ranking and code/math/reasoning verification performed by vetted subject-matter experts across software engineering, law, medicine, and finance.
Tooling & Platform-Agnostic Execution
Client-Hosted Evaluation Platforms
Our evaluators can work inside client-approved environments supporting response comparison, ranking, rubric scoring, preference labels, reviewer notes, and QA workflows.
COMPARISONRANKINGSCORINGQA
Proprietary Client Consoles
Reviewers can operate within client-owned RLHF or model-evaluation systems through approved secure access, following your prompt sets, evaluation criteria, ranking protocol, reviewer instructions, safety taxonomy, and review stages.
CLIENT UIVPNPOD
Josisoft Managed Evaluation Workspaces
When no production environment is available, we can configure controlled project workspaces around your prompts, response sets, preference rubric, reviewer roles, calibration tasks, and QA/adjudication stages.
CONTROLLEDCALIBRATEDMANAGED
Real-World RLHF Applications
PROMPT
Summarize the policy.
RESPONSE APREFERRED
PROMPT / RESPONSE / PREFERENCEGeneral-Purpose Language Models
Collect structured human preferences across helpfulness, relevance, clarity, correctness, completeness, and instruction-following tasks for broad language-model evaluation and improvement workflows.
CONTEXT
Customer requests a concise answer.
1DIRECT · RELEVANT
2VERBOSE · PARTIAL
Conversational AI & Assistants
Compare assistant responses across dialogue scenarios to evaluate tone, context handling, instruction adherence, usefulness, refusals, and conversational quality.
DOMAIN · OPERATIONS
TERMINOLOGY PASSPROCEDURE 4 / 5CONTEXT PASS
DOMAIN / RUBRIC / SCOREDomain-Specific AI Systems
Run preference tasks using domain-specific prompts, terminology, scenarios, and evaluation rubrics for enterprise or specialized language-model programs.
MODEL ACHECKPOINT 12
VSMODEL BCHECKPOINT 14
HUMAN PREFERENCE · A
MODEL A / MODEL B / HUMANModel Version Comparison
Compare outputs across model versions, checkpoints, configurations, or training stages using consistent human preference protocols and controlled evaluation sets.
Security, Compliance & Workforce Governance
Mandatory Bilateral NDAs
Every annotator, QA reviewer, and project manager signs an NDA before accessing project assets.
Security & Clean-Room Training
Personnel are trained on data confidentiality: strict restrictions on screen sharing, zero tolerance for screen recording or screenshots, and supervised session management.
Governed Physical Delivery Hub
On-premise operations at our central Durgapur facility enforce controlled local networks, restricted USB and removable media ports, and supervised work environments.
Isolated Hybrid Pods
Each client is assigned a dedicated team working in siloed environments, preventing cross-project data contamination and maintaining domain context.
CLIENT DATA BOUNDARY
CONTROLLED ACCESS
ISOLATED PODNDA · VPN · SUPERVISION
START A PROJECT
Request a Pilot BatchStart With a Calibrated RLHF Pilot.
Share a representative prompt set, candidate responses, preference rubric, scoring criteria, and acceptance rules with our delivery team. We will calibrate reviewer decisions, complete a controlled pilot batch, analyze disagreement and difficult preference cases, and return the sample for acceptance before production scaling.