Human-validated training data | Pilot-to-scale delivery | Multimodal coverage

Josisoft Technologies

HomeData Collection IndustriesHow We WorkAboutCareers / Join as an AnnotatorContactGet in Touch
CHAIN-OF-THOUGHT REASONING

Expert Human Verification and Rationale Data for Complex Multi-Step AI Reasoning

A correct final answer often conceals flawed intermediate logic, while an incorrect calculation can obscure a sound problem-solving strategy. Josisoft provides credentialed subject-matter specialists to author step-by-step reasoning traces, score intermediate derivations for Process Reward Models (PRMs), and pinpoint logical breakdowns across advanced mathematical, technical, and domain-specific tasks.

Talk to a Specialist
REASONING OPERATIONS

Core Chain-of-Thought & Reasoning Capabilities

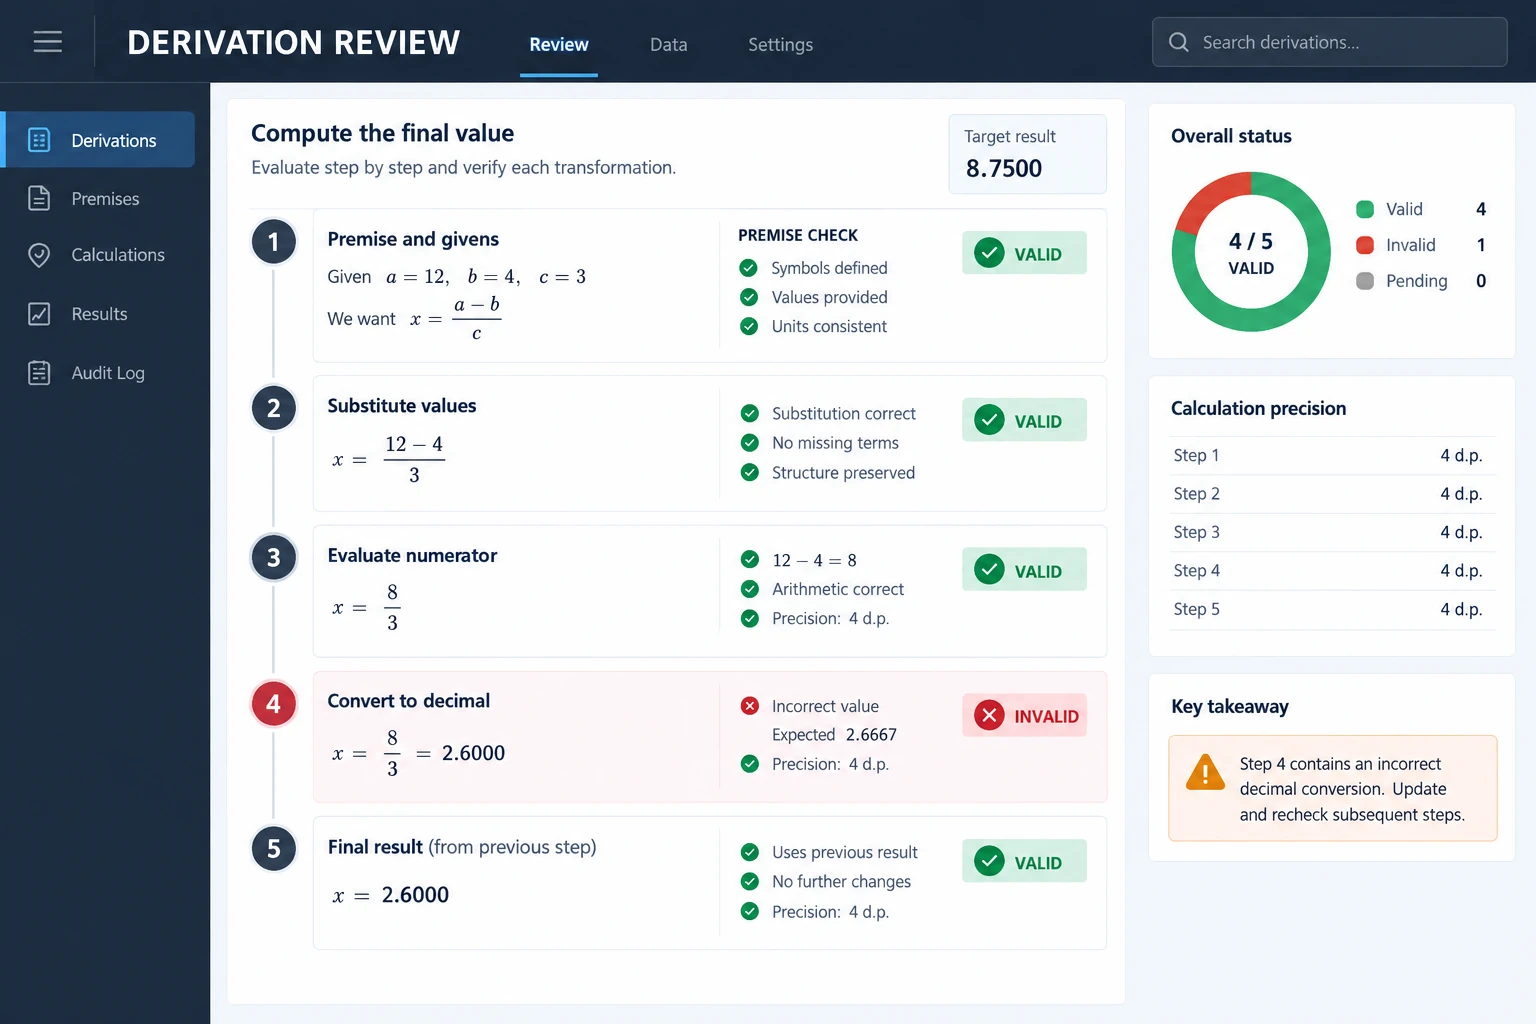
Step-by-Step Derivation & Intermediate Logic Verification

Granular human auditing of intermediate reasoning steps to verify factual validity, mathematical precision, deductive rigor, and premise consistency rather than judging model accuracy on final answers alone.

Process Reward Model (PRM) Credit Assignment

Dense step-level annotation attributing discrete positive, neutral, or negative credit to each intermediate token span or reasoning node to train process-supervised reward models.

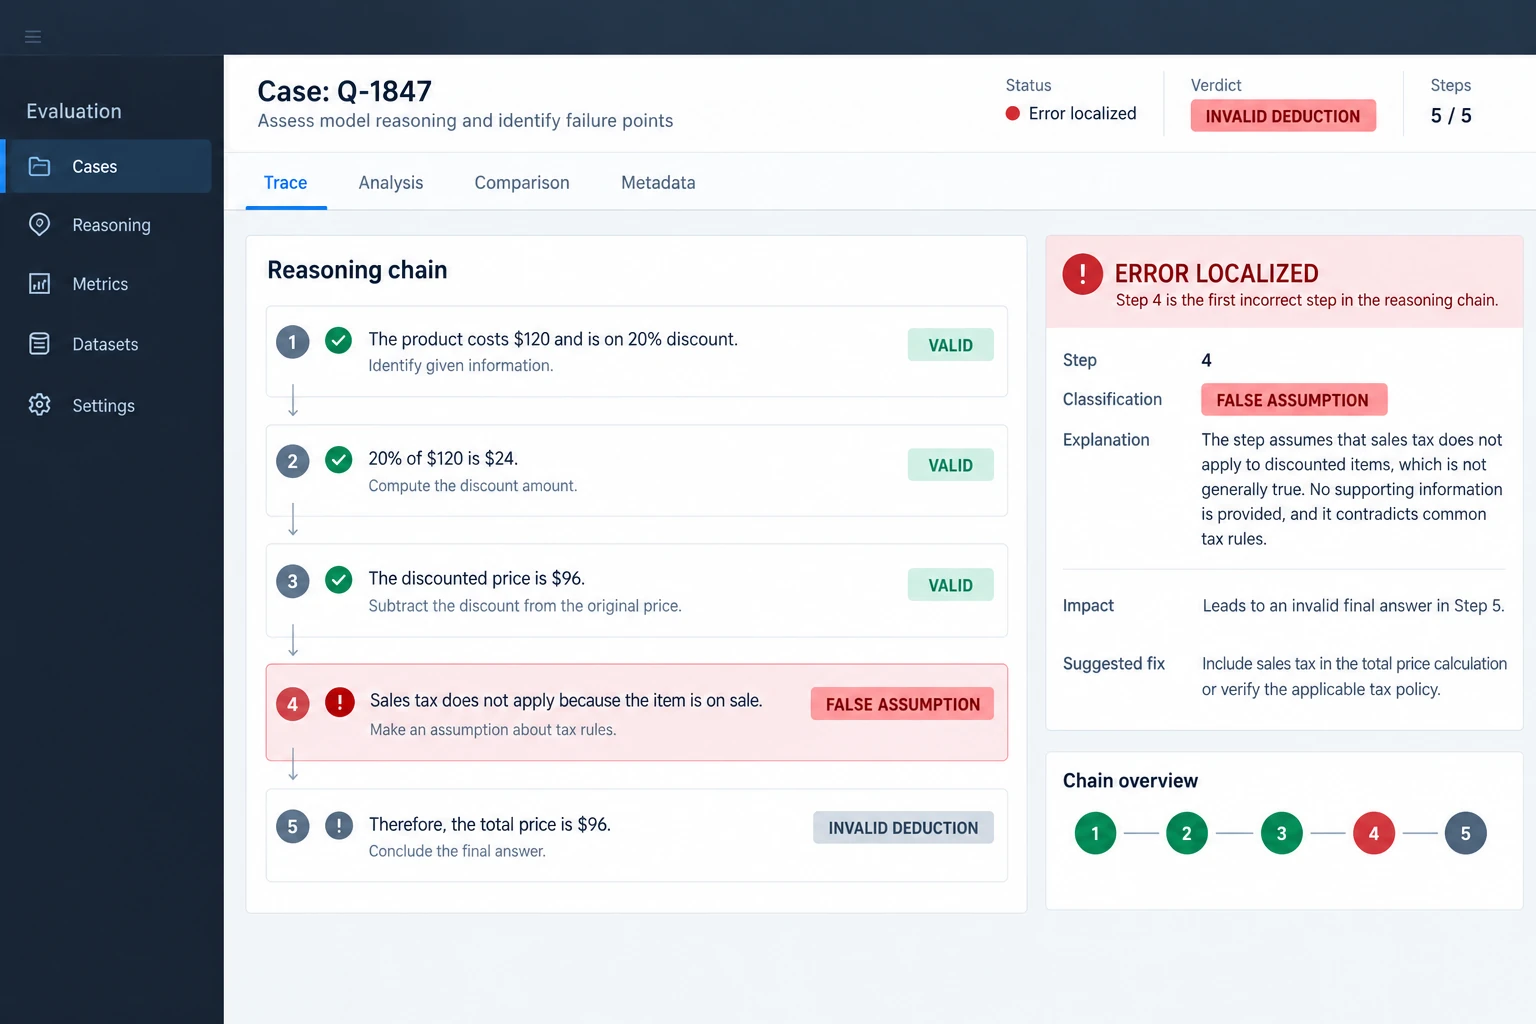
Error Localization & Fallacy Attribution

Pinpointing the exact inflection step where a reasoning chain derails, classifying the specific failure mode—including computational slips, false assumptions, hallucinated axioms, or faulty deductive jumps.

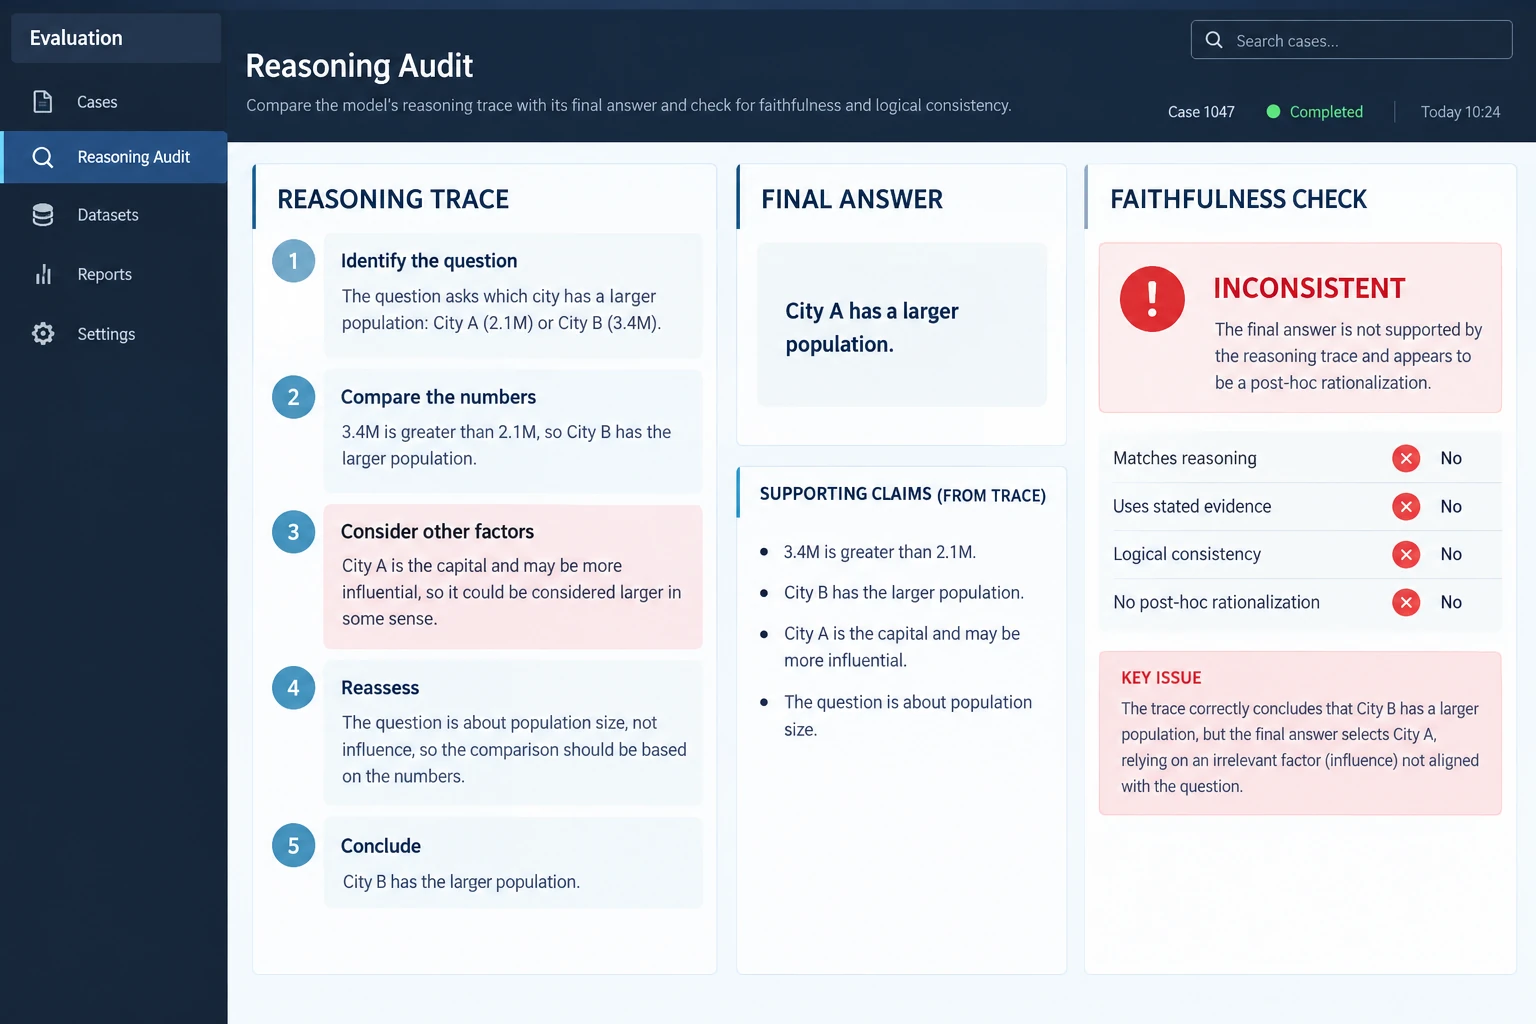
Faithfulness & Final-Answer Consistency Auditing

Auditing whether the model's stated final answer logically and honestly derives from its own chain-of-thought trace, detecting instances of unfaithful rationalization, post-hoc justification, or lucky guesses.

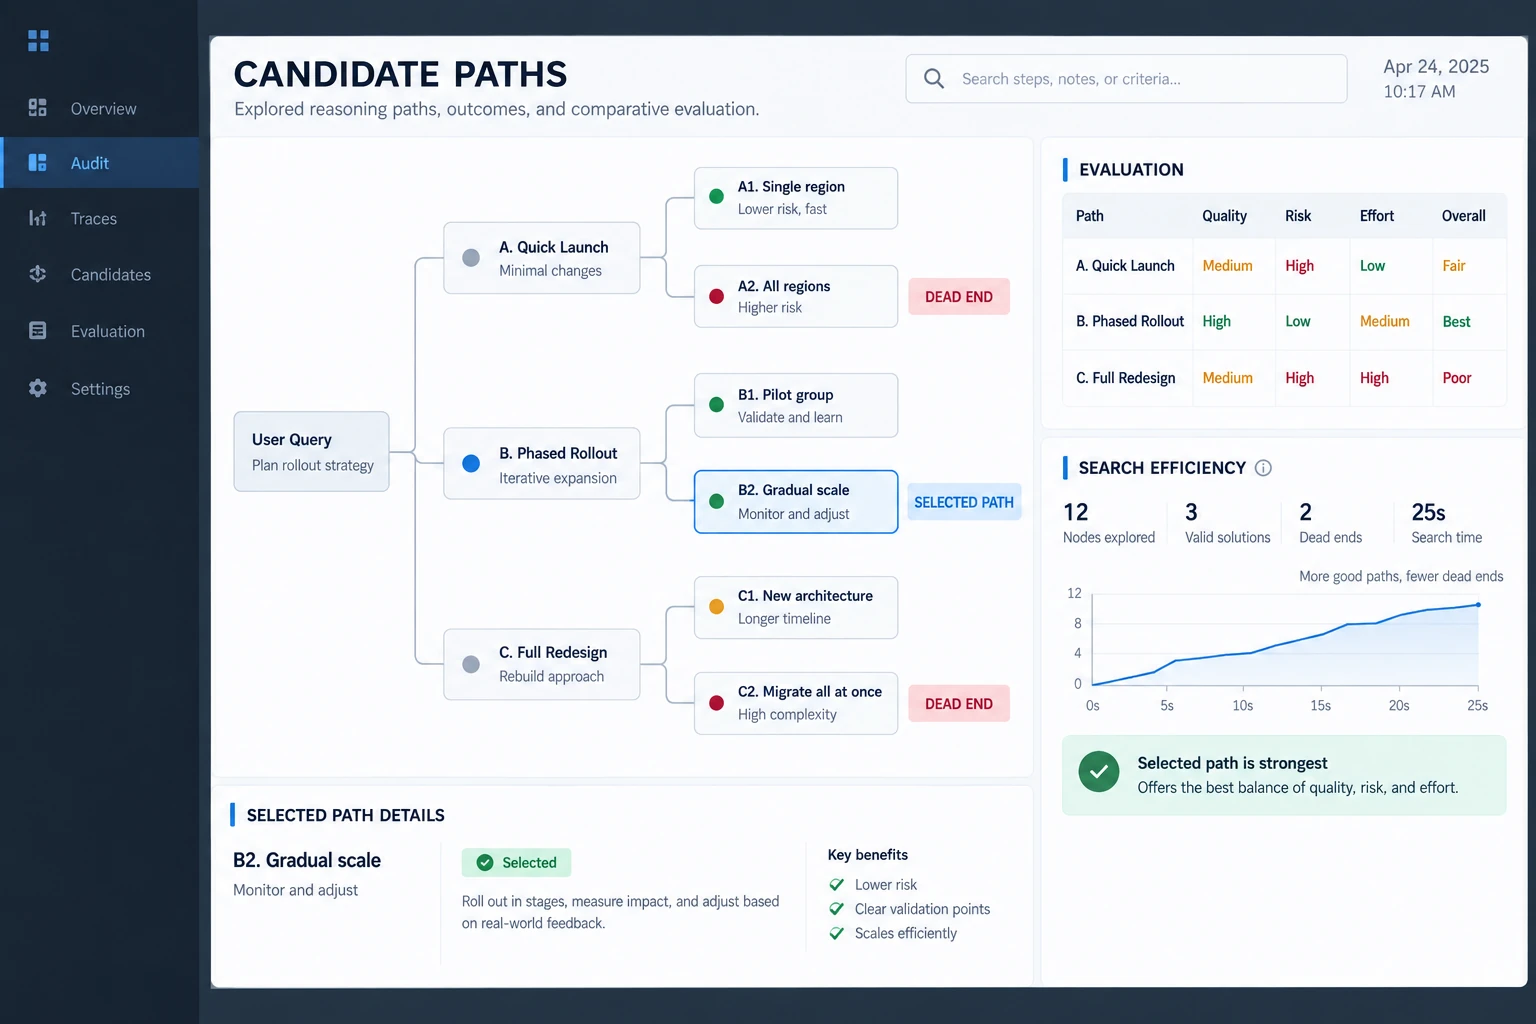
Tree-of-Thought (ToT) & Multi-Path Exploration Auditing

Comparative evaluation of divergent reasoning paths, assessing alternative problem-solving branches to identify optimal derivations, prune unproductive dead ends, and grade search efficiency.

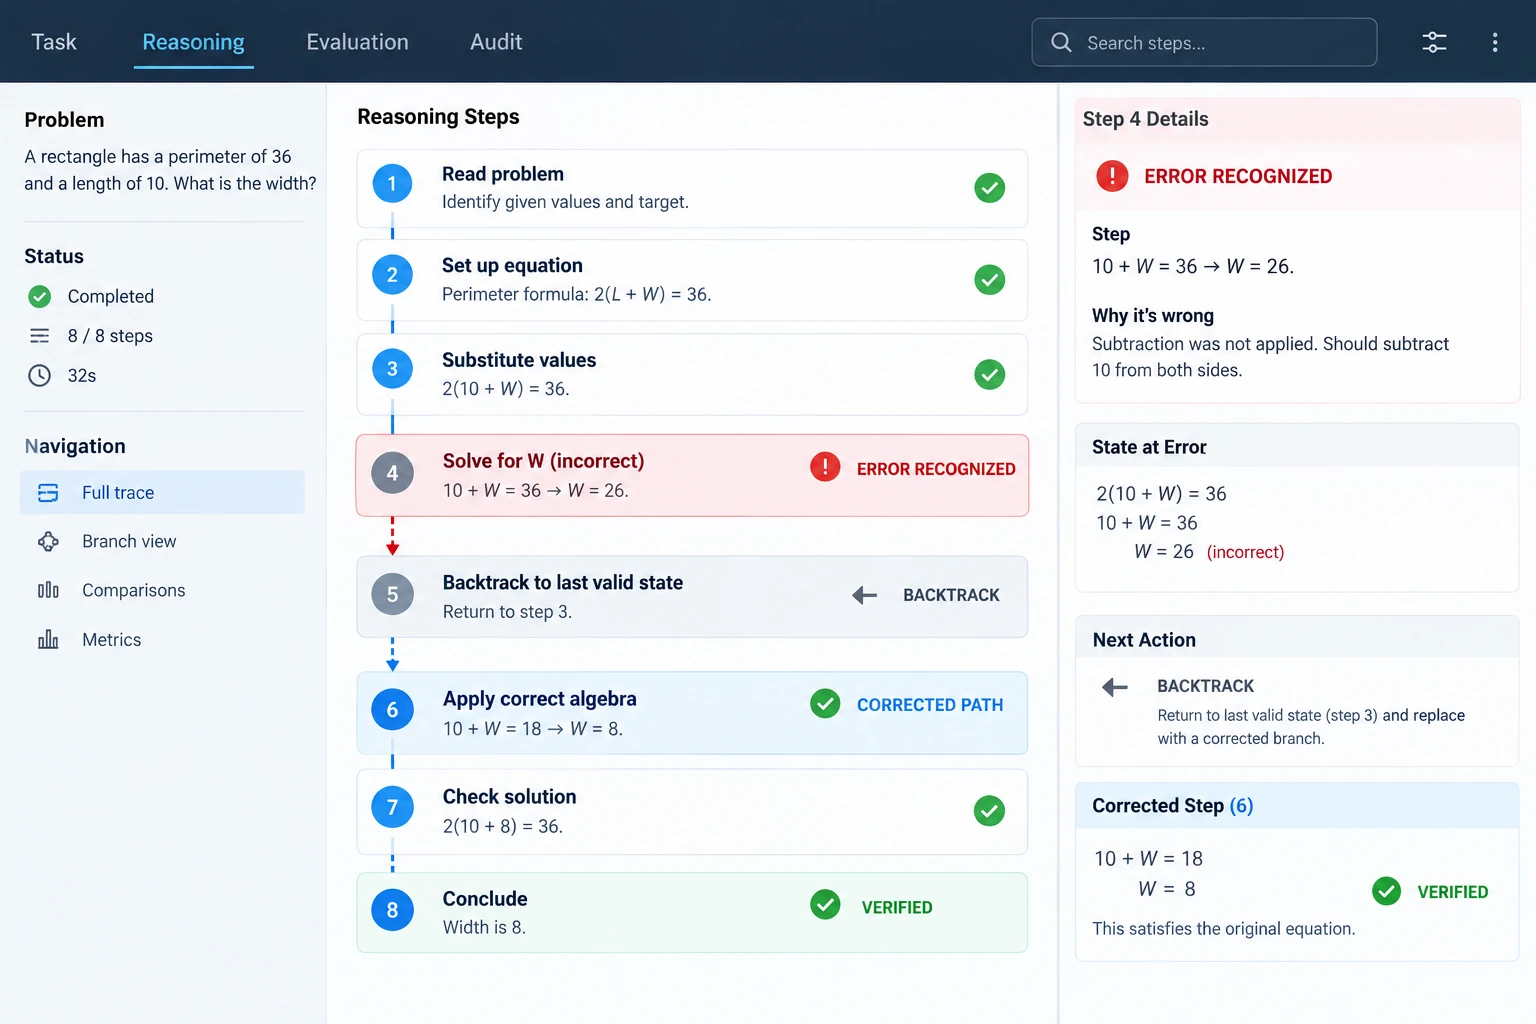
Backtracking, Self-Correction & Reflection Verification

Evaluating the model's capacity to recognize internal calculation or logical errors mid-generation, backtrack to previous valid reasoning states, and successfully pivot to correct solutions.

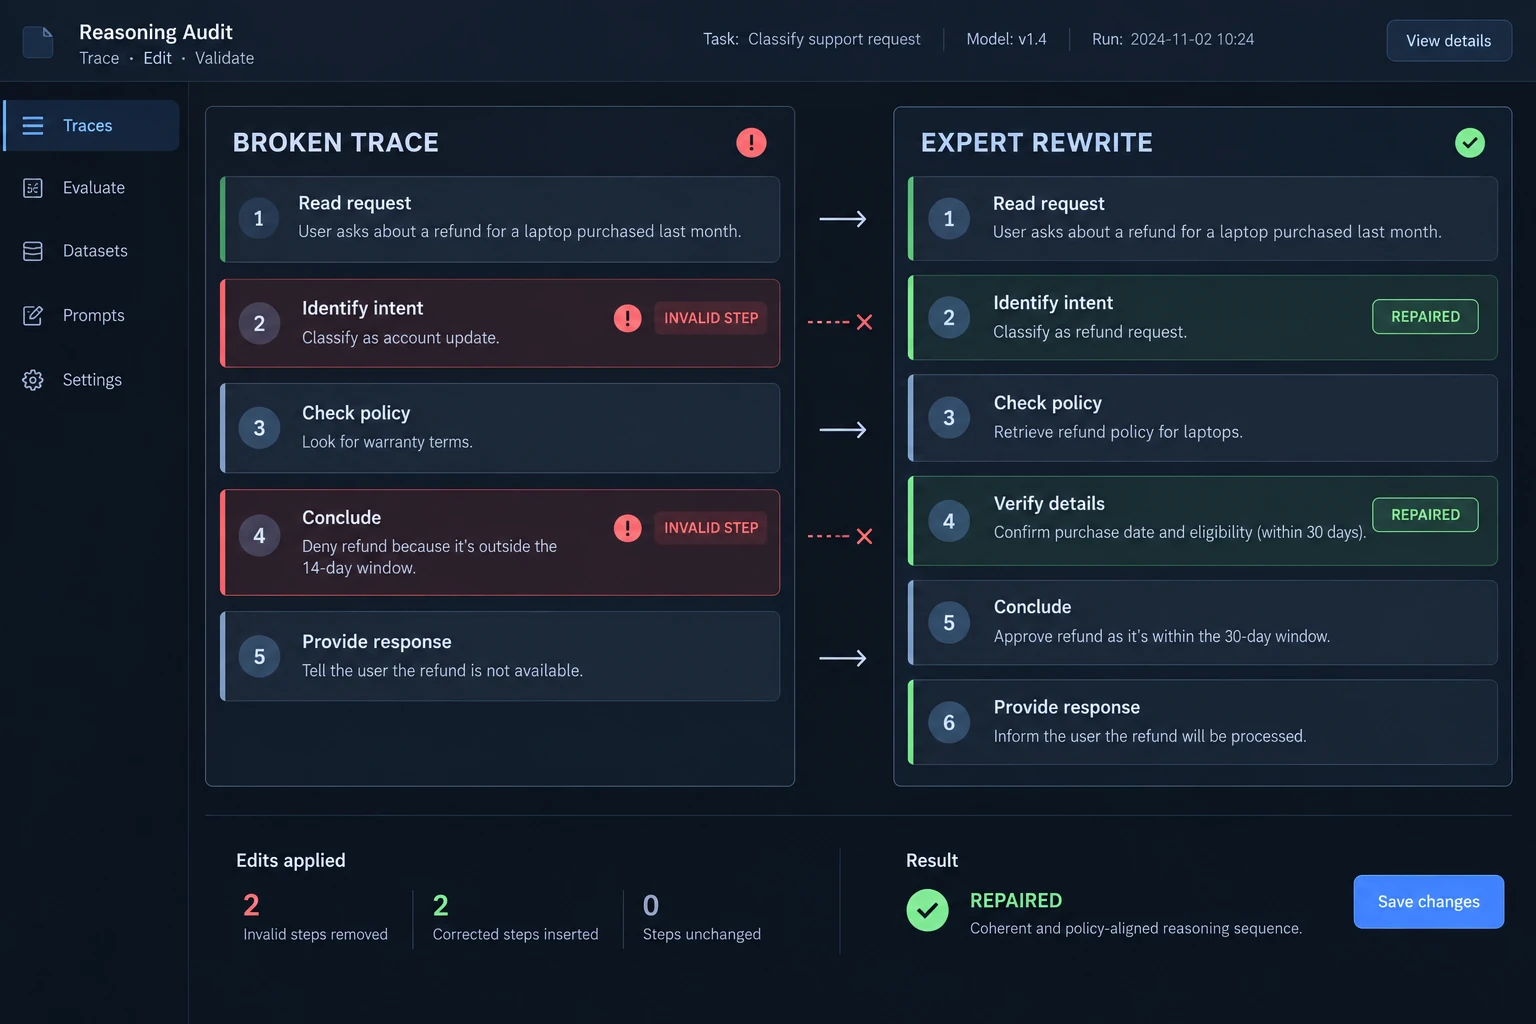
Broken Step Rewriting & Trajectory Repair

Expert human intervention where annotators take fractured model reasoning chains, prune invalid intermediate derivations, and author corrected logical steps to salvage high-quality training trajectories.

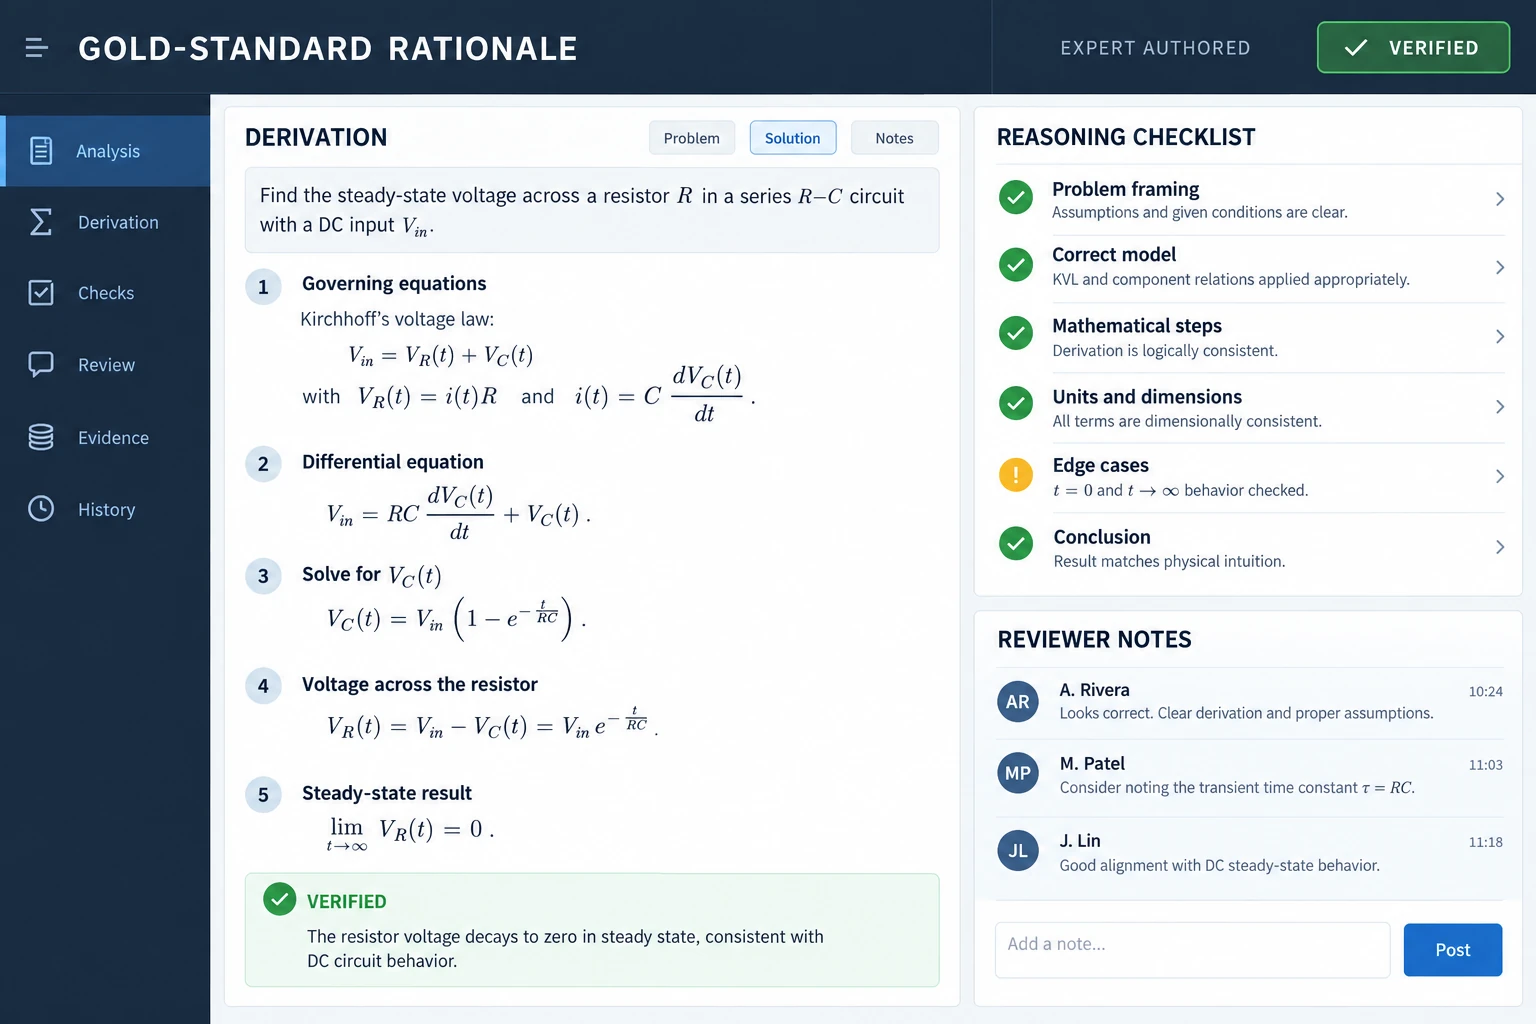
Domain-Expert Gold-Standard Rationale Authoring

End-to-end authoring of exhaustive, step-by-step thinking traces written by vetted mathematicians, software engineers, and research scientists to train reasoning-first foundation models.

FLEXIBLE DELIVERY

Tooling & Platform-Agnostic Execution

01

Client-Hosted Evaluation Platforms

Our evaluators can work directly inside client-approved environments supporting multi-step responses, intermediate-step labels, rubric scoring, error tagging, reviewer notes, and QA workflows.

STEPSRUBRICSERRORSQA
02

Proprietary Client Consoles

Reviewers can operate within client-owned reasoning-evaluation systems through approved secure access, following your task taxonomy, step criteria, error labels, scoring rubric, reference logic, and review stages.

CLIENT UIVPNPOD
03

Josisoft Managed Evaluation Workspaces

When no production evaluation platform is available, we can configure controlled project workspaces around your task sets, reasoning outputs, scoring rubric, error taxonomy, evaluator roles, and QA/adjudication stages.

CONTROLLEDCALIBRATEDMANAGED
DEPLOYED CONTEXT

Real-World Complex Reasoning Applications

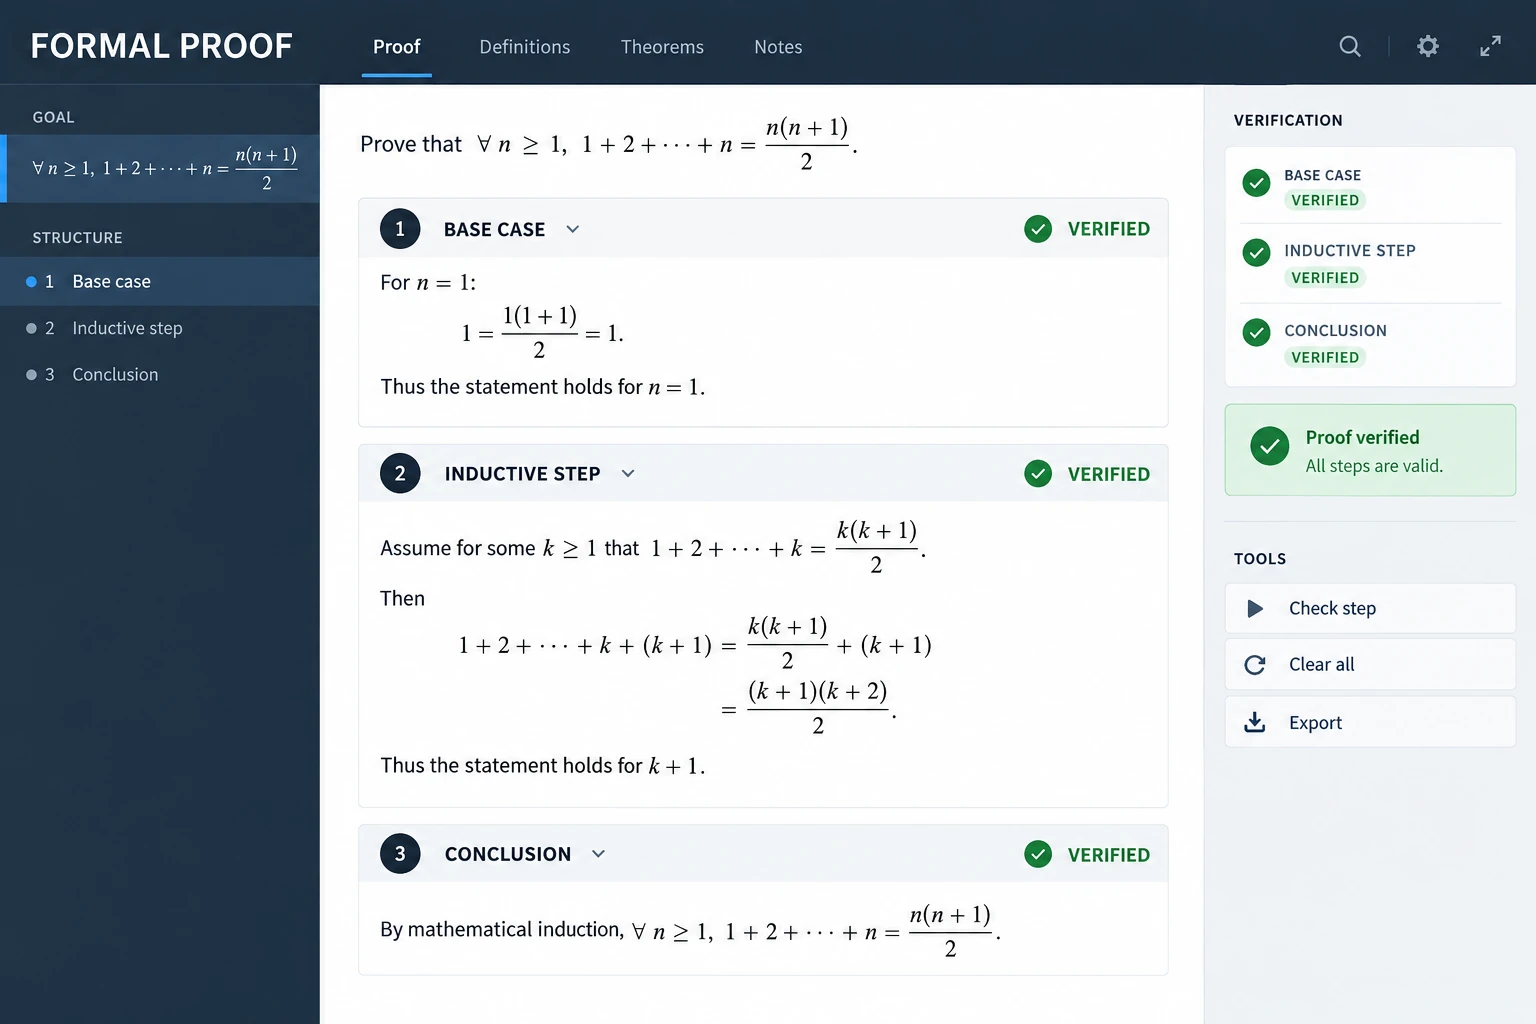
Mathematical & Formal Quantitative Proofs

Auditing step-by-step derivations across discrete mathematics, calculus, linear algebra, theorem proving, and quantitative problem-solving to ensure rigorous mathematical correctness.

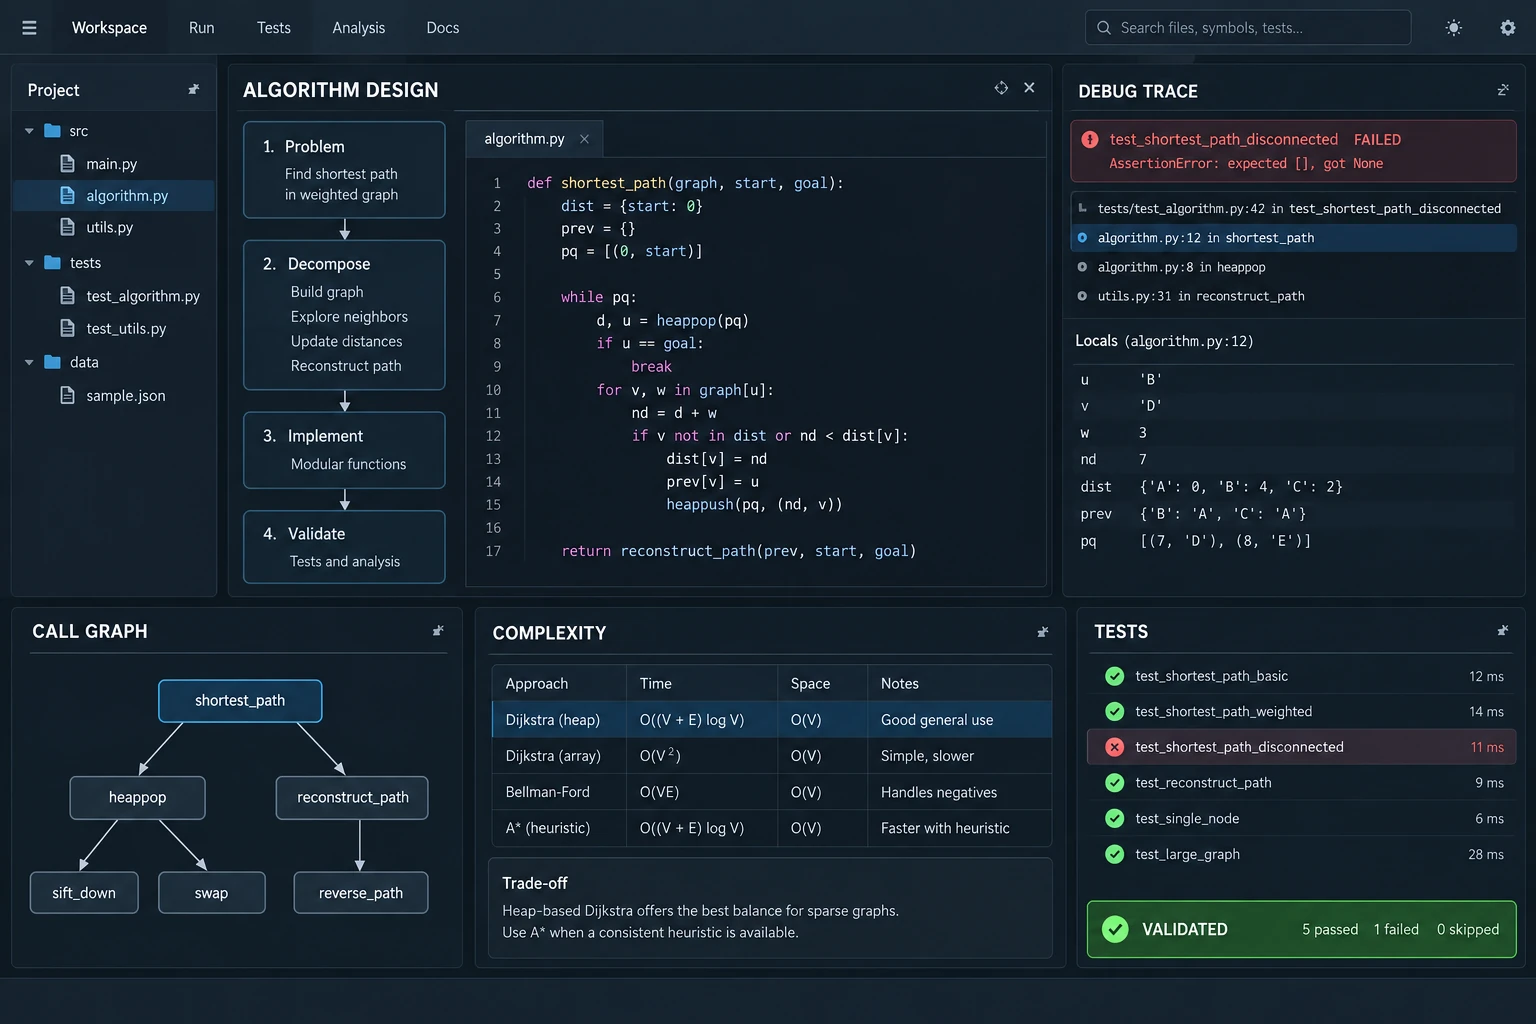
Code Architecture & Algorithmic Derivation

Evaluating multi-step algorithmic design, systematic code debugging, complexity trade-off analyses, and recursive logic decomposition across full-stack software stacks.

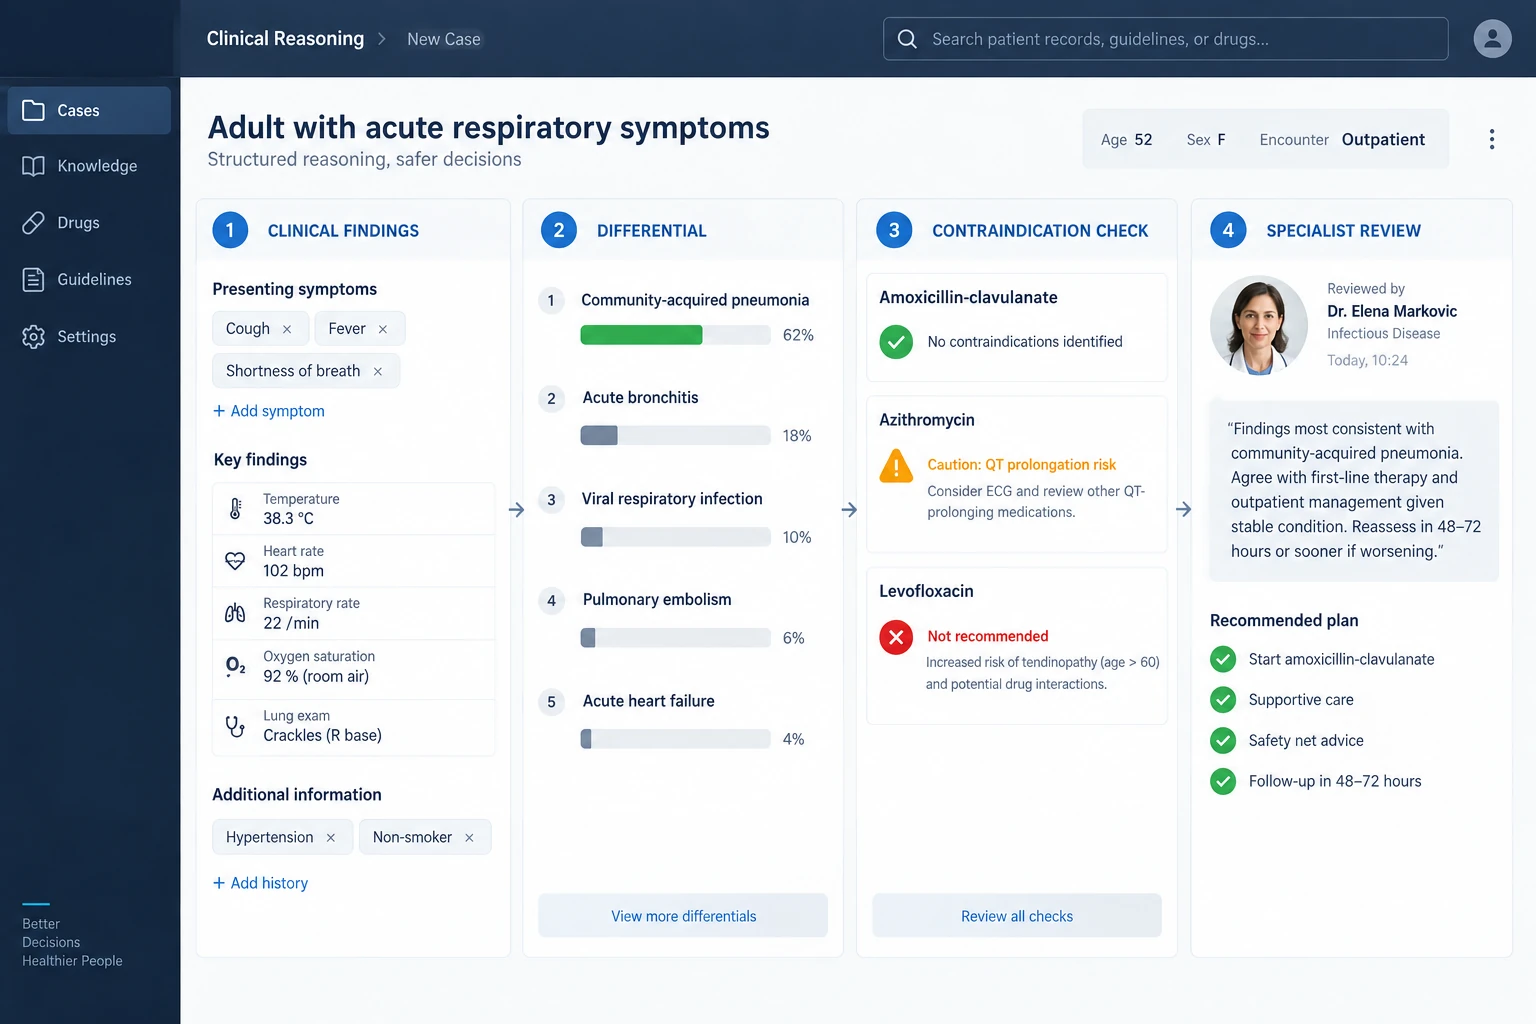
Clinical Diagnostics & Pharmacological Pathways

Reviewing multi-step diagnostic reasoning, contraindication cross-referencing, differential diagnosis formation, and treatment plan logic executed by credentialed medical doctors.

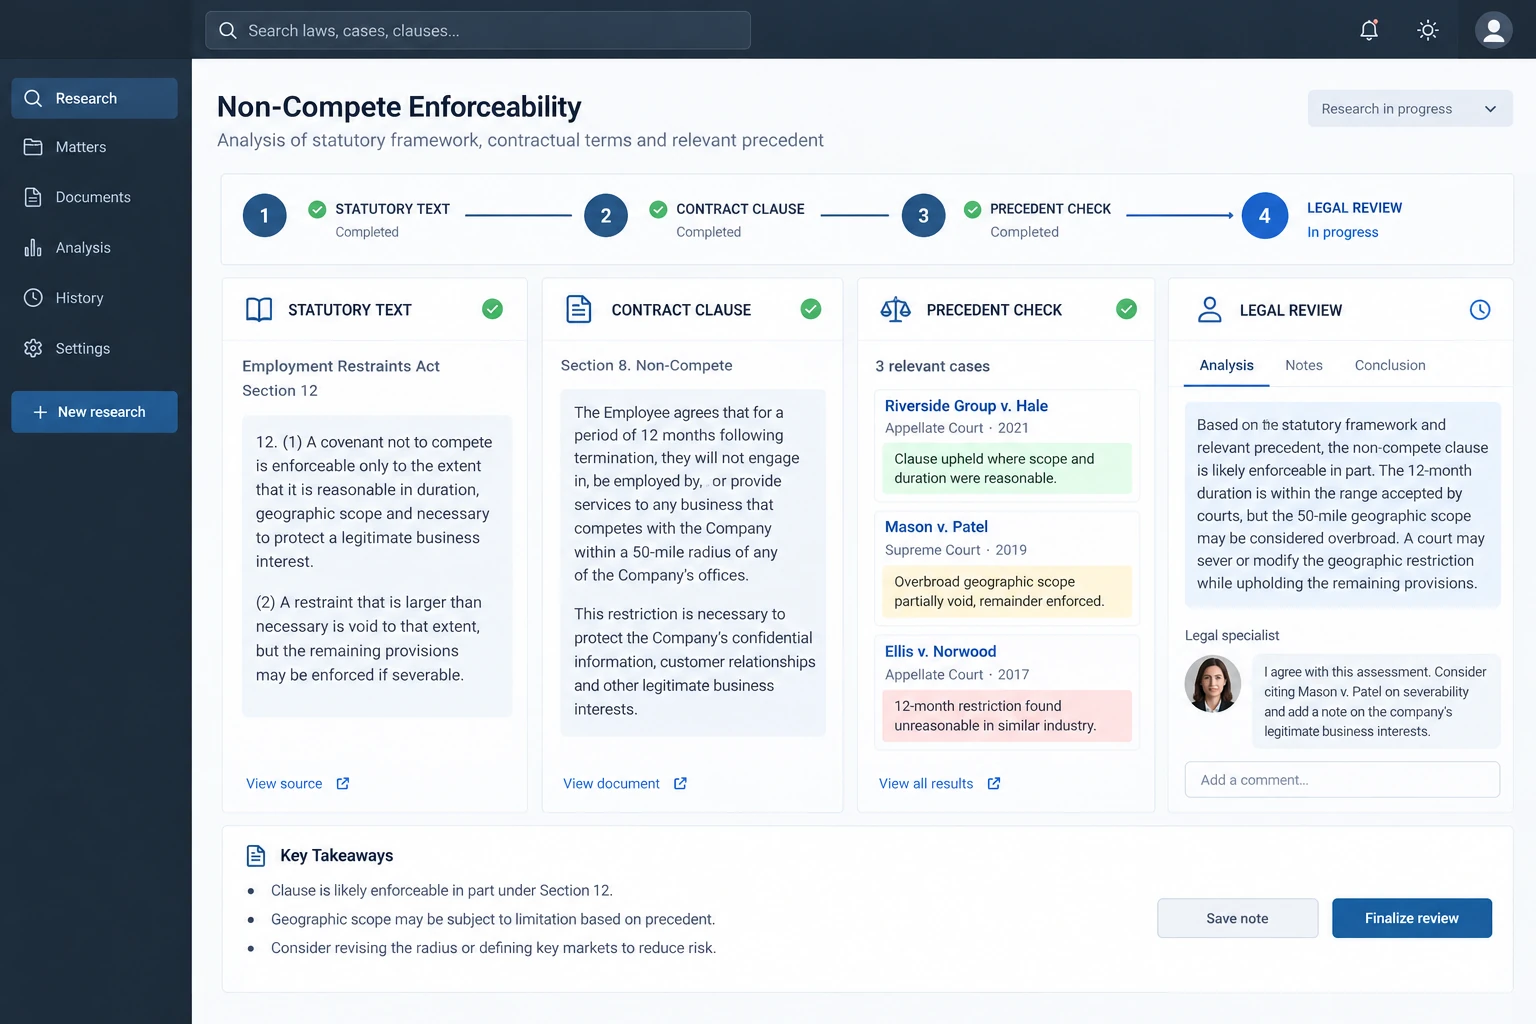
Legal & Regulatory Statutory Reasoning

Auditing statutory interpretations, multi-jurisdictional compliance deductions, contract loophole analysis, and precedent cross-referencing conducted by legal specialists.

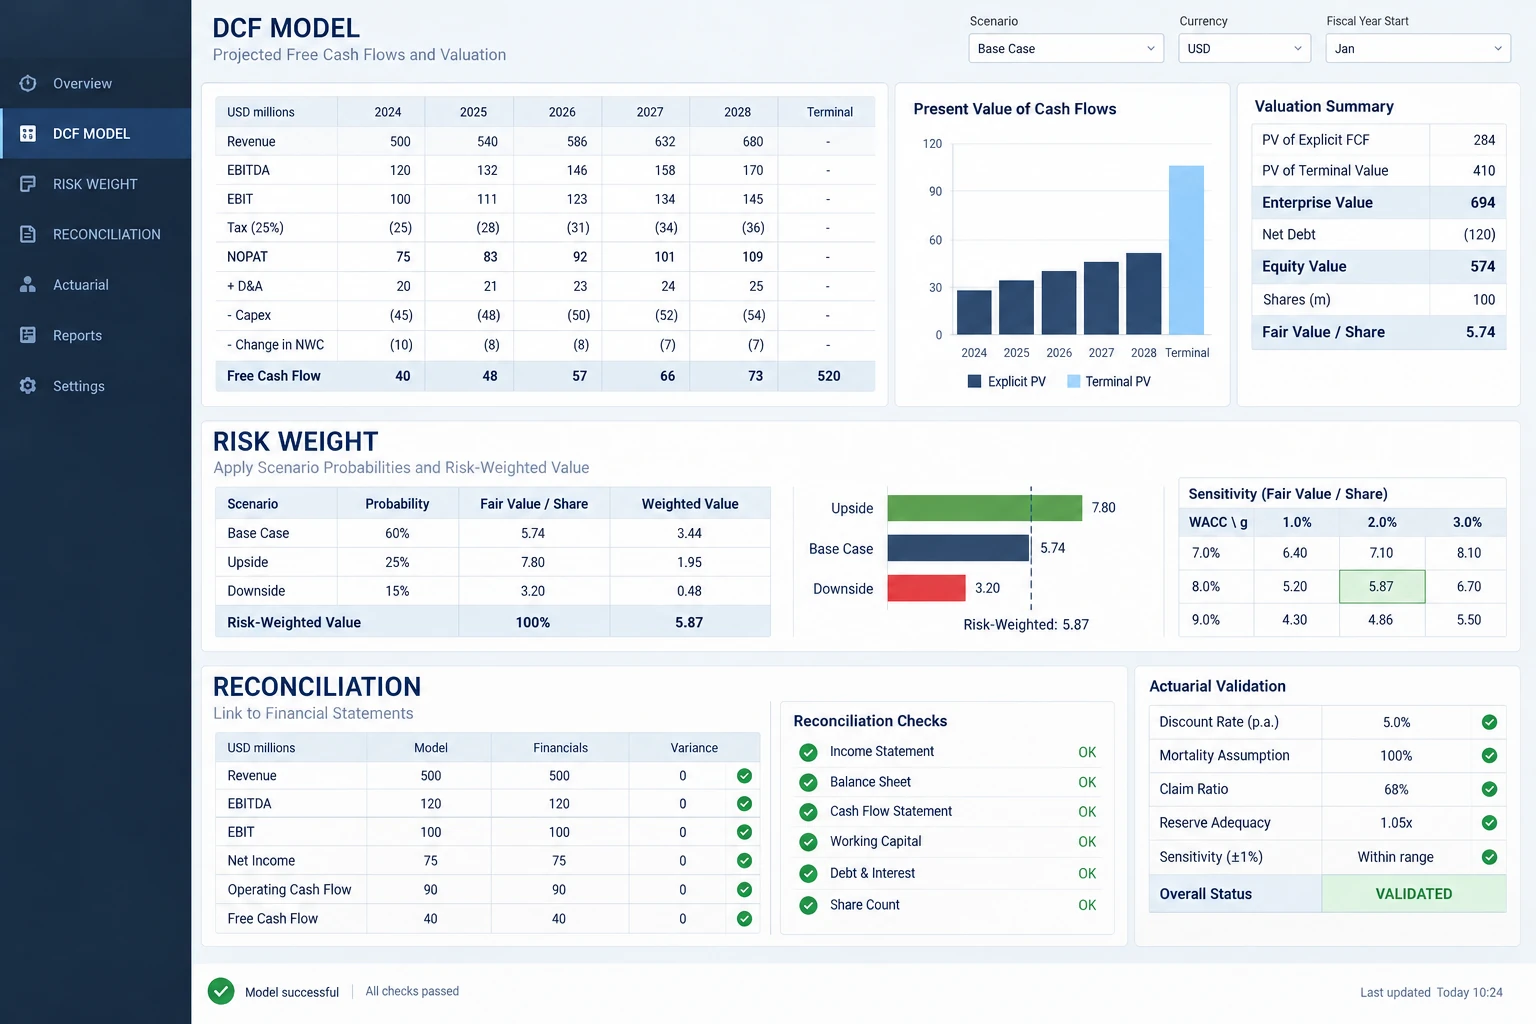
Financial Modeling & Actuarial Valuation

Validating layered DCF derivations, risk-weighted asset calculations, financial statement reconciliation, and tax liability computations against regulatory frameworks.

Scientific Discovery & Experimental Analysis

Verifying causal deduction chains, hypothesis formulation, chemical synthesis pathways, and experimental data interpretation across biology, chemistry, and physics.

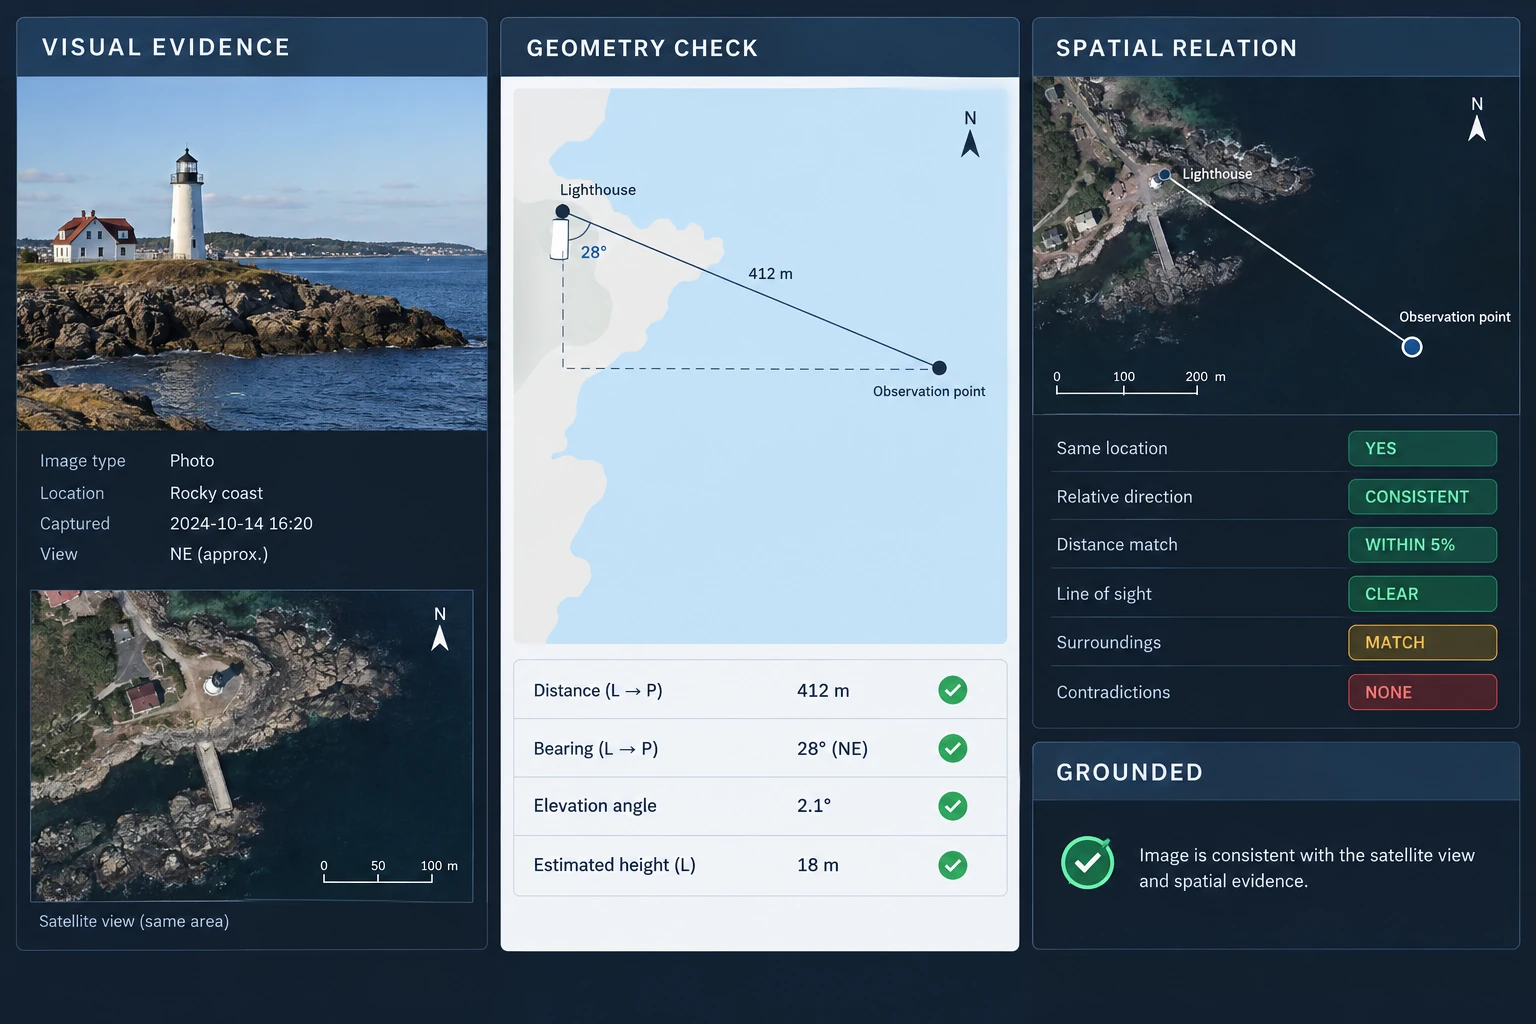
Multimodal Spatial & Visual Logic

Auditing joint image-text reasoning steps—such as interpreting complex schematic diagrams, geometric figures, satellite imagery, and surgical video frames.

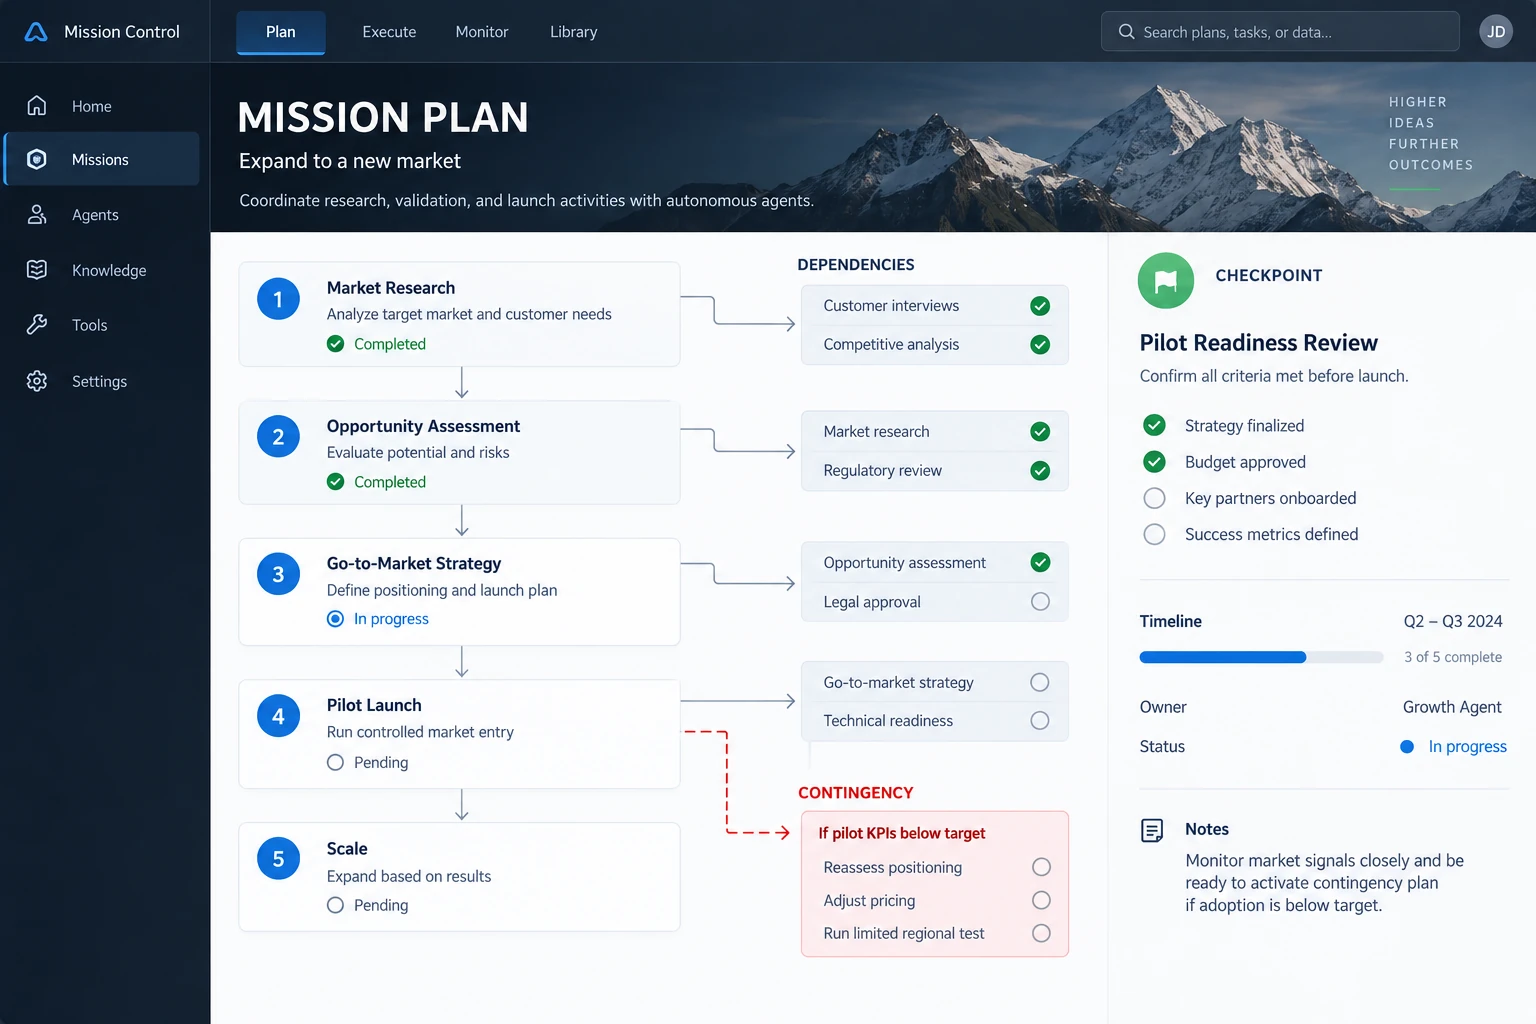
Autonomous Agent Multi-Step Planning

Evaluating long-horizon strategic plans generated by autonomous agents, ensuring sequential sub-goal decompositions, dependency handling, and contingency fallbacks are logically sound.
CONTROLLED OPERATIONS

Security, Compliance & Workforce Governance

01

Mandatory Bilateral NDAs

Every annotator, QA reviewer, and project manager signs an NDA before accessing project assets.

02

Security & Clean-Room Training

Personnel are trained on data confidentiality: strict restrictions on screen sharing, zero tolerance for screen recording or screenshots, and supervised session management.

03

Governed Physical Delivery Hub

On-premise operations at our central Durgapur facility enforce controlled local networks, restricted USB and removable media ports, and supervised work environments.

04

Isolated Hybrid Pods

Each client is assigned a dedicated team working in siloed environments, preventing cross-project data contamination and maintaining domain context.

START A PROJECT

Start With a Calibrated Reasoning Evaluation Pilot.

Share a representative task set, model-generated reasoning outputs, reference logic, scoring rubric, error taxonomy, and acceptance criteria with our delivery team. We will calibrate evaluator decisions, complete a controlled pilot batch, review ambiguous steps and difficult error cases, and return the evaluation sample for acceptance before production scaling.

Request a Pilot Batch